
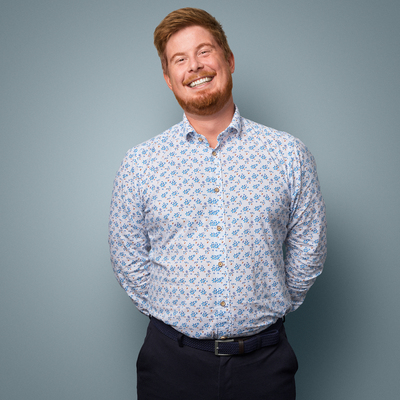
Kristian Johannesen
Databricks MVP & Champion | Partner and Principal Architect @Distinkt
Aalborg, Denmark
Actions
Kristian is an experienced data professional who has spent the past 6 years working with the Microsoft and Databricks stack.
Extensive experience in Data Engineering and BI workloads across the entire Azure stack - with specific emphasis on Azure Databricks
Area of Expertise
Topics
Can I DAB it? - Yes you can!
Declarative Automation Bundles should be a key part of any modern Databricks platform today.
In this fast-paced talk I will try and show you why, by highlighting what you can (and should) do with DABs - and where there might still be a need for other tools such as Terraform.
From Pipelines to Context - the role of the Context Engineer
With the rise of Agentic capabilities across all data platforms, Data Engineers have been tasked with a new area of expertise: Context Engineering
In this session we will dive into the topic of context, through the lens of a Data Engineer. More specifically, we will look at how to design your Databricks Platform in the most efficient way, to ensure that context is a part of everything from architectural decisions to governance and business definitions.
We will cover both more general questions such as:
- What is good context?
- How do we build it?
- What about maintenance, updates and CI/CD?
But also dive into more feature-specific topics such as Databricks Ontology, Metric Views, Skills and Agent Instructions.
You will leave with a good understanding of how to manage context as an input for your agentic applications such as Genie
Best Practices for Power BI on Databricks
In this session we will dive into the best practices of building Power BI on top of a Databricks platform.
There has been quite a bit of commotion in the past year, related to the integration between the platforms - but a lot of the best practices that have existed for years are still there, and despite what you might think, the two platforms work very well together!
However, both platforms offer opportunities to handle end-to-end BI workloads. So, which platform does what when they have to work together?
This will be the main focus of the session. To uncover how to make this happen in the best way possible, we will dive into topics such as:
- Architectural trade offs
- Semantic Modelling
- Refresh Patterns
- Data Governance
You should leave with an understanding of which integration patterns work , and which to steer clear off, when working with Databricks and Power BI together.
Genie in a bottle: An introduction to Conversational BI on Databricks
This Genie does not grant you 3 free wishes, but it still might be the missing piece for enabling self-service at a wider scale, as long as you enable it correctly. In this session I will show you all the good basics of how to do that correctly!
If you are new to the world of Databricks, the concept of Genie might already be both confusing and intriguing. It seems to be everywhere at once, but also have so many different flavors. In this session we will focus on the end-user experience of Genie (formerly Databricks One) and Genie Spaces.
The session will cover an introduction to Genie, covering the following topics and capabilities:
- Setup and configuration
- Data foundation
- Security and Governance
- Consumptions paths
- Reinforced learning and training
Expect a session that is demo-heavy and gives you a good hands-on impression of what Genie can do for your analytics environment.
Accelerating your migration to Databricks
Migration projects are everywhere, and with the rise of monolithic platforms such as Databricks, getting your legacy estate migrated is becoming increasingly important.
We will start with a broader look at what a successful migration project looks like:
- Planning what do we need to do
- Sourcing data
- Code Migration
- Test and reconciliation
Then we will dive in to Databricks Lakebridge and take a look at how the tool is supporting migration to a Lakehouse in Databricks.
In this session I will take you through what the tool does, how it works, and show practical examples of working with the tool.
In addition, you will get my honest takes, based on personal experience, on how the tool can support your upcoming migration. How to make the most of it, and what to avoid.
Master Governance in Databricks Unity Catalog
Unity Catalog provides a host of different opportunities for governing and securing your data.
In this session we will move past the basics of user administration through simple privileges and dive into the world of policy-driven and domain-oriented access, covering automatic data classification, Attributed-based Access Policies (ABAC) and secure data sharing.
Learn to apply appropriate policies, tagging and row level filters and see how a policy-driven access control empowers a consistent approach to governing and securing your data, across all types of different applications such as SQL endpoints, Dashboards and even GenAI applications such as Genie.
Data Point Prague 2026 Sessionize Event
New Stars of Data #10 Sessionize Event
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top