
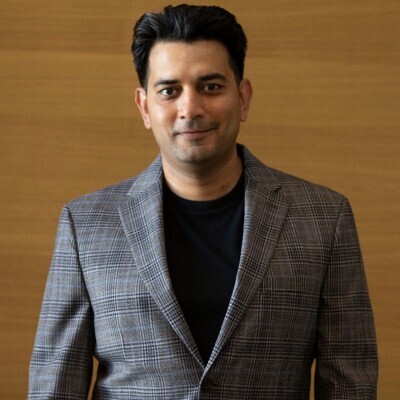
Ritvik Pandya
Engineering leader focused on distributed systems, cloud platforms, and pragmatic architecture.
San Francisco, California, United States
Actions
Ritvik Pandya is an engineering leader specializing in distributed systems, Kubernetes platforms, cloud-native architectures, and large-scale payment infrastructure.
He enjoys working at the intersection of architecture, platform engineering, and cross-team collaboration, helping organizations build systems that scale both technically and operationally. His experience spans platform engineering, payment processing, developer platforms, cloud modernization, and high-performance distributed systems.
Throughout his career, Ritvik has led initiatives involving Kubernetes, service mesh technologies, API gateways, event-driven architectures, observability platforms, and mission-critical payment systems. His work has focused on improving system reliability, reducing latency, increasing throughput, and enabling engineering teams to deliver complex solutions with confidence.
Ritvik is passionate about sharing practical lessons learned from building and operating systems at scale. His talks focus on real-world engineering challenges, including distributed systems design, platform engineering, cloud-native architectures, observability, reliability engineering, service mesh adoption, API management, and modern software delivery practices.
As a speaker, author, reviewer, and engineering leader, he aims to bridge the gap between architectural theory and production reality by providing actionable insights that engineering teams can apply immediately.
Area of Expertise
Topics
The Negative Diagnosis: Why "Not an Ingress Issue" Is the Most Valuable Verdict
Most observability systems are built to detect problems and surface them.Most automation is built to react and remediate. Both miss something important: the most valuable verdict an automated diagnostic system can produce is often "this is not my problem."
This talk argues that for any observability system claiming to attribute latency or root cause,the negative diagnosis -the confident statement that a subsystem is not the cause -is more valuable than the positive detection.It changes the social contract of incident response:from "everyone investigates everything" to "the system that owns the signal owns the diagnosis."
Drawing on work building component-level latency attribution inside an edge proxy,this talk presents the negative diagnosis as a design pattern: how to build it,why its threshold structure differs from positive detection,why it is harder to defend,and why systems that know when not to fire are the systems engineers actually trust enough to deploy autonomously.
AI : Learned Execution Graphs for Real-Time Anomaly Detection & Drift Classification in APIs
API ingress controllers process requests through ordered sequences of middleware steps — authentication, authorization, validation, rate limiting, routing, service invocation, caching. We model this pipeline as a directed acyclic graph (DAG) learned from structured telemetry events, then apply graph-based anomaly detection and drift classification in real time at 1,600+ TPS.
The system emits one structured event per processing step, constructs per-endpoint execution graphs using sequence mining with statistical confidence thresholds, and learns per-node baselines (latency, dependency, execution frequency). Three graph intelligence capabilities emerge:
(1) Graph-based anomaly attribution — compute per-node deviation ratios against learned baselines to identify the exact bottleneck node and its dependency. In production, this pinpointed a 41x deviation at a single graph node that was invisible to service-level monitoring, reducing root cause identification from 2-3 hours to under 30 seconds.
(2) Graph structural drift detection — compare observed node sequences against the learned graph topology to detect missing nodes (mandatory processing step silently skipped), reordered nodes (middleware misconfiguration), and unexpected new nodes (unauthorized middleware injection). Traditional monitoring reported "system healthy" when a mandatory node was removed — latency dropped, errors at zero — only the learned graph comparison detected the structural change.
(3) Per-client graph fingerprinting — learn client-specific execution graph profiles using exponential moving averages. Detect when a client's graph traversal pattern changes, classify the cause (client behavior change vs. configuration drift vs. infrastructure failover) using KL divergence on node-visit distributions, and apply graph-aware adaptive control scoped to specific nodes rather than entire endpoints.
The execution graph model also enables a novel approach to retry storm detection: analyzing idempotency key entropy at graph nodes to classify traffic as legitimate growth vs. retry amplification, and returning cached responses at the specific graph node rather than rejecting requests — breaking the retry amplification loop.
Production system processing high TPS. Attendees will learn the graph construction methodology, the anomaly attribution algorithm, and concrete patterns for adding learned graph intelligence to any middleware pipeline.
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top