
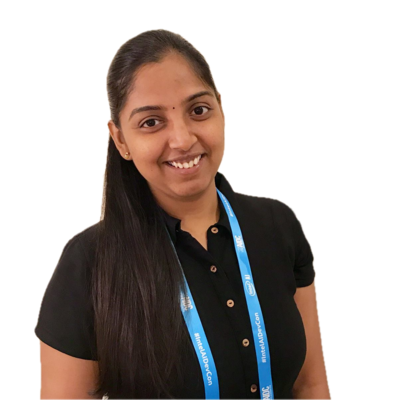
Abinaya Mahendiran
CTO - Nunnari Labs| Independent Researcher | Community Enabler @ AI Tamil Nadu
Coimbatore, India
Actions
Abinaya Mahendiran is an AI leader with nearly thirteen years of experience in building and scaling end-to-end AI/ML systems. She specializes in Natural Language Processing (NLP), Generative AI, and MLOps, with a strong foundation that bridges data science and engineering. She currently serves as the Chief Technology Officer at Nunnari Labs, Coimbatore, where she leads the development of production-grade AI solutions.
Her work is centered on advancing inclusive and multilingual AI, particularly improving representation for underrepresented languages like Tamil. She has contributed to the Aya dataset, supporting the creation of high-quality multilingual instruction data for large language models. As part of GEM (General Evaluation for Multilingual), she has worked on developing fair and comprehensive evaluation benchmarks using both automated and human metrics. She has also contributed to NL-Augmenter, focusing on improving the robustness and reliability of NLP systems.
Beyond research and engineering, Abinaya is deeply involved in community building. She co-leads AI Tamil Nadu (formerly AI Coimbatore), a grassroots initiative that brings together students, researchers, and engineers to collaborate on AI and Tamil computing. Through workshops, annotation sprints, and open discussions, she has enabled broader participation in AI development.
She is also committed to improving representation in technology. As Program Manager for the Hidden Voices initiative at IIT Madras, she has worked to reduce gender gaps in digital knowledge platforms. Through the Vidhai initiative, she supports early exposure to AI and open source, particularly encouraging young women to enter the field.
An active mentor and speaker, Abinaya continues to advocate for building AI systems that are not only powerful but also inclusive and representative.
Links
Area of Expertise
Topics
Tracing the Failure: Debugging a Production RAG System in a Language Your Tools Don’t Speak
RAG systems are increasingly used to build question-answering applications over domain-specific data. However, when a RAG application produces a wrong answer, identifying where the failure occurred is often the harder problem. This session uses PonniRAG (https://ponniarchive.com/), a production open-source RAG system built over a historical Tamil magazine archive from 1947–1955, containing 1,700+ articles across 108 issues and 487 contributors, to walk through the debugging process from query to answer.
The session examines how each stage of the RAG pipeline behaves differently when working with Tamil, a morphologically rich language with historical spelling variations and OCR-generated text. The session will focus on:
- Query understanding & routing: identifying retrieval questions versus metadata lookups and handling Tamil-specific question patterns.
- Filtering & retrieval: dealing with morphological variations, embedding-model conventions, recall and precision, and why hybrid search does not always solve the problem.
- Chunking & context assembly: handling article boundaries, OCR noise, historical context, conflicting information, and preserving metadata for provenance and citations.
- Evaluation & observability: identifying failures that are invisible at the model level and validating whether the evaluation tooling itself works correctly for non-Latin languages.
The session is grounded in real production failures and the fixes that were implemented, rather than a generic RAG architecture or a list of best practices. One example is an evaluation metric that reported near-zero scores because its tokenizer stripped non-Latin characters; another was the need to create a 50-question native-language ground-truth set because a suitable benchmark did not exist.
Attendees will leave with a practical, stage-by-stage debugging approach that can be applied to their own RAG systems, including:
- Localizing the failure before tuning the model
- Evaluating retrieval, chunk quality and context independently
- Treating embedding conventions and metadata as correctness requirements
- Auditing evaluation and observability tooling for multilingual systems
Although Tamil is the primary case study, the approach is applicable to practitioners building AI systems for other underserved Asian languages where tooling, benchmarks and language-specific infrastructure are limited.
Testing Machine Learning Systems
The objective of this talk is to throw some light on how machine learning systems can be tested using the software engineering principles. Though machine learning systems are completely different from traditional software systems, we can still leverage all the design and testing paradigms from software engineering and apply it to any machine learning system.
In this talk, we will look at how ML systems are different from the traditional software systems, what are the principles of testing a traditional software system and how it can be applied to a machine learning system.
A Primer on MLOps
This session will focus on the basics of MLOps which is one the emerging areas in the industry. It will give an overview of what exactly is MLOps, how it's different from DevOps, what components makes the MLOps framework, what open source frameworks are available and can be leveraged and how can a ML/Data Science team can benefit from it by doing so.
Building Human-in-the-loop pipeline in MLOps
The objective of this talk is to throw some light on how the productionized models can be improved iteratively by adopting Human-in-the-loop pipeline (Active learning strategy and human annotation) in an MLOps lifecycle.
The assumption is that any team that is building an end-to-end MLOps platform will have the following pipelines in place,
1. Data pipeline - To ingest data from several sources and to standardize them
2. Feature engineering pipeline - To perform feature engineering and save metadata
4. Training/Retraining pipeline - To perform actual training and retraining of the model (with data and model versioning)
5. Monitoring pipeline - To monitor the productionized model and check its performance
6. Inference pipeline - To provide predictions on real-time data
Models do fail in production because of the data/concept drift and is identified by the monitoring pipeline. To improve the degrading model, retraining is performed using more labelled data. Data is available in abundance, but labelled data is not, depending on the use case. Annotating data is a tedious task but an essential and unavoidable one. Since most of us leverage transfer learning to fine-tune for down-stream tasks on limited data, identifying the right data points (in the dataset) to annotate is imperative. Active learning will help in identifying the data points that are not confidently predicted by the base model and human annotation can be performed on the chosen subset of data. Model can then be retrained iteratively with the sampled and annotated data. Having this human-in-the-loop pipeline in place will help build a better data flywheel (More data leading to better model leading to more users who can provide more data and the cycle continues).
TECH(K)NOW Day on INTERNATIONAL WOMEN'S DAY 2022 Sessionize Event
Abinaya Mahendiran
CTO - Nunnari Labs| Independent Researcher | Community Enabler @ AI Tamil Nadu
Coimbatore, India
Links
Actions
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top