
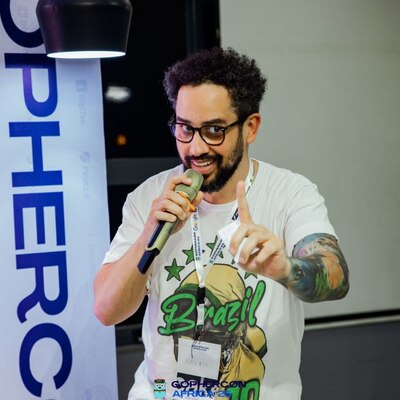
Alex Rios
Principal Engineer @Memed
Curitiba, Brazil
Actions
Alex is a Principal Engineer at Memed, where he builds developer platforms and internal tools that empower engineering teams across the organization. With 17+ years of experience, he's the author of System Programming Essentials with Go and Learning Zig, and writes about staff engineering and systems thinking on Substack and his personal blog. Alex speaks regularly at international conferences and is passionate about data-oriented design, making complex systems understandable, and helping engineers grow into technical leadership roles.
Links
Area of Expertise
Topics
United We Compile: Cross-Compiling CGO
Cross-compiling CGO projects has long been a challenge for Go developers. While CGO enables access to the vast ecosystem of C and C++ libraries, it introduces complexities like dependency management, slow builds, and the pitfalls of dynamic linking with glibc or musl. In this talk, we’ll explore how Zig—a modern systems programming language—can simplify cross-compilation workflows for CGO projects, enabling faster, cleaner, and more portable builds.
Tug-of-Code: The battle for efficient iteration in Go
Iterators are a powerful tool for traversing custom data structures, enabling clean, reusable, and efficient code. In this talk, we’ll explore how iterators work in Go, from the familiar `for-range` loop to advanced patterns like pull-based iterators and mutation during iteration.
It’s Tool O’Clock: Time to upgrade your Go workflow
In this session, we’ll explore the latest enhancements to `go tool` that streamline dependency management, improve performance, and simplify developer workflows. Learn how tool directives in `go.mod` eliminate cumbersome workarounds like `tools.go`, how caching speeds up repeated executions, and how structured JSON output makes debugging builds and tests easier than ever. We’ll also discuss new features like GOAUTH for private module authentication and embedding VCS info into binaries. Be prepared to have actionable insights to modernize your Go projects.
Weak Pointers in Go: Implementation Deep Dive
Go's weak pointer implementation looks deceptively simple: 'Make' and 'Value', that's it. But underneath lies an elegant design involving indirection objects, a handle table, careful GC integration, and an equality guarantee that no other major language provides. How does 'wp1 == wp2' remain true after the object is collected? Why is the indirection object exactly 8 bytes? How does the GC know when to zero the pointer without causing races?
This talk dissects the implementation: the indirection layer that makes equality stable, the handle table that enables efficient lookups, the GC write barrier integration, and why generics were required for a type-safe API. We'll read the actual runtime code and understand the design constraints that shaped each decision.
Main idea: Go's weak pointer uses an 8-byte indirection object between the weak pointer and the target. The weak pointer holds a pointer to this indirection object (not to the target). When the target dies, the GC zeros the indirection object's pointer field—but the indirection object itself survives. This is why 'wp1 == wp2' stays true after collection: both still point to the same indirection object.
Questions this talk answers:
- Why the indirection layer? Without it, you have a race: the GC wants to collect the object while user code reads the weak pointer. With indirection, the GC atomically zeros one pointer (in the indirection object), and user code atomically reads it. No races, no locks needed on the hot path.
- How does the handle table work? Creating a weak pointer for the same object twice must return equivalent weak pointers (same indirection object). The runtime maintains a table mapping objects to their indirection objects. This uses the object's address as a key, with careful handling when objects move during GC.
- Why is generics required? Before Go 1.18, a type-safe weak pointer API would need one function per type or use 'interface{}' everywhere. Generics enable 'weak.Pointer[T]' where 'Value()' returns '*T' without casts. The implementation uses unsafe internally but presents a safe API.
- How does the GC integration work? The GC must zero indirection objects for dead targets but not follow weak pointers as roots. This requires special handling in the mark phase: indirection objects are tracked separately, and their target pointers are processed in a second pass after determining liveness.
- What makes the equality guarantee possible? Indirection objects are never freed while any weak pointer references them. They form a secondary lifetime: the target can die, but the indirection object persists until all weak pointers to it are gone. This is tracked via reference counting on the indirection objects.
Attendees will understand the implementation well enough to read 'src/runtime/weak.go' themselves, know why each design decision was made (indirection for races, handle table for deduplication, generics for type safety), and appreciate how the equality guarantee—unique to Go—enables patterns impossible in Java or Python where weak references become incomparable after collection.
A possible adaptation for intermediate-level :
For an intermediate audience, the talk balances why weak pointers exist with how to use them effectively, without diving into runtime implementation details. I'd start with the 15-year history—why Go resisted, what changed, to give context for the design constraints. The core content would cover the two-method API (Make and Value), the mental model of the indirection layer (without implementation details), and the equality guarantee as a feature to rely on rather than a mechanism to understand. Practical patterns get significant time: building a WeakCache that shrinks under memory pressure, implementing canonical maps for deduplication, and the observer pattern without preventing cleanup. The talk would address common mistakes: checking Value() twice (the object could die between checks), forgetting that weak pointers don't prevent collection (obvious but often misunderstood), and when not to use weak pointers (short-lived objects, low memory pressure). Attendees would leave able to implement weak-pointer-based caches and understand when weak pointers solve their problem vs. when a regular cache with eviction policy is simpler.
Value Canonicalization in Go
Comparing two identical 1MB strings takes 1.3 milliseconds. Comparing two 'unique.Handle[string]' values takes 0.31 nanoseconds. That's 4.1 million times faster.
The 'unique' package: a standard library solution for value canonicalization (also called interning). This talk explores the problem it solves, how it works internally with GC-integrated weak pointers, and when you should (and shouldn't) reach for it.
Main idea: The 'unique' package solves two related problems—redundant memory allocations and expensive O(N) string comparisons—by storing only one copy of each distinct value and returning handles that compare in O(1) time via pointer equality.
Questions this talk answers:
- Why is string comparison expensive? Go strings are compared byte-by-byte. Two identical 1MB strings require scanning all 1 million bytes. With 'unique.Handle', the same comparison is a single pointer check: 0.31 nanoseconds vs 1.3 milliseconds.
- How does it avoid memory leaks? The package uses weak pointers internally. When no handles reference a value, it becomes eligible for garbage collection automatically. No manual cleanup required.
- When should I use it? High duplication rate (>30% repeated values), frequent comparisons, or memory pressure from redundant strings. Poor fit: unique values, short-lived data, or forgetting to store handles (defeating the purpose).
- What's the gotcha with pointer fields? Structs containing pointers compare pointer addresses, not pointed-to values. Two structs with '*string' fields pointing to equal strings but different addresses produce different handles.
Attendees will understand when interning helps vs. hurts (with benchmarks showing the crossover points), learn the internal weak pointer mechanism, and see how 'net/netip.Addr' uses 'unique' to efficiently represent IP addresses—the real-world case that motivated the package after a 10-year journey from Issue #5160.
When Tests Become Slot Machines: Deterministic Concurrency with synctest
Your concurrent test passed 47 times. Then it failed. You ran it again. It passed. Congratulations, you now have a slot machine.
Testing concurrent Go code has always meant choosing between slow (sprinkle time.Sleep everywhere) and flaky (accept random failures) or something like a "broken clock" abstraction. Go 1.25's synctest eliminates this choice entirely. Tests that took 20 minutes now run in the blink of an eye. Tests that failed randomly now pass deterministically. Every time!
This talk shows how synctest creates isolated "bubbles" where time is fake, goroutines can be observed at rest, and "this should not have happened" becomes testable.
Main idea: The 'testing/synctest' package creates isolated "bubbles" where time is fake and goroutines can be observed at rest. Inside a bubble, 'time.Sleep(1*time.Hour)' completes in microseconds, and 'synctest.Wait()' returns only when all goroutines are "durably blocked", waiting on channels, timers, or mutexes with no way to proceed without external input.
Questions this talk answers:
- Why can't time.Sleep prove a negative? To test "nothing happens for 5 seconds," you'd sleep 5 real seconds. But that doesn't prove nothing happened, it proves nothing happened *yet*. And if you sleep too short, you get flaky failures. synctest solves this: fake time advances instantly, and 'Wait()' tells you when all goroutines have stabilized.
What is "durably blocked"? A goroutine is durably blocked when it's waiting on something that won't resolve without external action: a channel receive with no sender ready, a timer that hasn't fired, a mutex held by another blocked goroutine. 'synctest.Wait()' returns when ALL bubble goroutines reach this state. This is deterministic—no timing assumptions needed.
How does fake time work? Inside a bubble, 'time.Now()', 'time.Sleep()', 'time.After()', and 'time.Timer' all use simulated time. The runtime advances this clock when goroutines are durably blocked on timers. A test can "sleep" for hours without burning wall-clock time.
What are the limitations? Real I/O (network, disk) involves goroutines outside the bubble—they won't be tracked. Subtests create separate bubbles. Global goroutines (started before the bubble) aren't isolated.
Attendees will know how to convert flaky tests to deterministic ones (with before/after examples), understand the "durably blocked" concept that makes it work, and recognize when synctest won't help. Tests that took 20 minutes with sleep-based synchronization now run in milliseconds.
Beginner-level adaptation:
For a beginner audience, the talk would focus on the problem (flaky tests) and the solution (replace time.Sleep with
synctest.Wait) without diving into runtime mechanics. I'd start by showing a real flaky test that passes 9 times out of10, then fails mysteriously in CI—a pain point every Go developer recognizes.
The core message: time.Sleep(100*time.Millisecond) is a guess, synctest.Wait() is a guarantee. Code examples would show simple before/after transformations: replace sleep with Wait, wrap the test in synctest.Run, done. The talk would cover the three things to remember: time is fake inside the bubble, Wait returns when goroutines have nothing to do, and real I/O breaks the isolation. Attendees would leave able to convert their existing flaky concurrent tests to deterministic ones using a mechanical pattern.
Advanced-level adaptation:
For an advanced audience, the talk would explore how synctest's bubble abstraction is implemented in the runtime and its edge cases. I'd examine how the runtime tracks goroutines belonging to a bubble, how fake time is implemented (the faketime clock, timer heap manipulation), and the precise definition of "durably blocked", blocked on a channel with no ready sender/receiver, a mutex held by another durably blocked goroutine, or a timer in fake time.
The talk would cover subtle failure modes: why a for { select { default: } } loop hangs Wait forever (never durably blocked), howruntime.Gosched() differs from blocking, and why goroutines started before the bubble aren't tracked. I'd also examine testing strategies for code that mixes real I/O with timers, how to structure tests when bubble isolation isn't enough, and the implementation differences between synctest.Run and synctest.Test. Attendees would leave understanding the runtime machinery well enough to debug when Wait hangs unexpectedly and design testable concurrent APIs from the start.
Hunting Goroutines: Go's Experimental Leak Detector
Somewhere in your program, there are goroutines that will never wake up. They're blocked on channel sends that will never complete, waiting on mutexes that nobody will unlock. They're not dead (the runtime still knows they exist), but they're not alive either.
Go 1.26 introduces an experimental goroutine leak detector that changes this. By leveraging the garbage collector's reachability analysis, it can distinguish "waiting for work" from "stuck forever".
[What attendees will learn]
- Why goroutine leaks are insidious: no crash, gradual accumulation
- Common leak patterns: early returns, orphaned senders, forgotten cleanup
- The insight: ask the GC about channel reachability
- How the detector temporarily "hides" channel references
- The new `_Gleaked` goroutine state in the runtime
- Using `pprof/goroutineleak` in tests and production
[Questions to highlight]
- What are the most common goroutine leak patterns?
- How do I add leak detection to my existing tests?
- How do I distinguish real leaks from false positives?
- Should I check for leaks in every test?
- How does the detector work with test subtests?
[Initial outline]
1. The problem: goroutines that never wake up
2. Why detection is hard: waiting looks the same as stuck
3. The insight: reachability implies wakeability
4. Asking the GC nicely: how to detect unreachable channels
5. The mechanism: hiding references, iterative marking
6. The new state: `_Gleaked` joins `_Grunning` and `_Gwaiting`
7. Using it: `pprof.Lookup("goroutineleak")`
8. Real bugs caught: CockroachDB (18), Kubernetes (14), Moby (11)
9. Integrating leak detection into your test suite
[Target audience]
Go developers who write concurrent code, maintain long-running services, or want to catch goroutine leaks before they hit production. The talk covers both practical usage and the elegant GC trick that makes it possible.
If the Program Committee prefers other levels for this subject:
For a beginner audience, the talk would focus on what goroutine leaks are and how to spot them, rather than implementation details. I'd start with the mental model: a goroutine leak is a goroutine that will never terminate, usually because it's blocked waiting on a channel that will never receive or send. The talk would emphasize practical detection, using runtime.NumGoroutine() in tests, the goleak package for automated detection, and reading goroutine dumps with pprof. Code examples would show common patterns that leak (unbuffered channels with no receiver, forgotten context cancellation, time.After in loops) and their fixes. The goal is that attendees leave able to add leak detection
to their test suites and recognize the three or four most common leak patterns in code review.
For an advanced audience: the talk would dive into why leaks happen at the runtime level and sophisticated detection strategies. We'd examine how the Go scheduler manages blocked goroutines, why a leaked goroutine consumes ~2KB of stack (which grows if it ever runs), and how it pins the memory it references. The talk would cover building custom leak detectors that track goroutine creation sites using runtime.Stack, integrating leak detection into production monitoring (not just tests), and analyzing complex leak scenarios involving multiple blocked goroutines forming a cycle. We'd also explore edge cases: goroutines blocked on finalizers, leaks hidden behind sync.Pool, and the interaction between leaked goroutines and the garbage collector. Code examples would include production instrumentation patterns and debugging real-world leak cascades.
Why Go Hides Its Spinlocks
A spinlock is the difference between pacing by the door versus taking a nap while waiting for a package. One burns CPU cycles. The other yields to the scheduler. Both have their place, but Go deliberately hides spinlocks from you.
This talk explains the core trade-off between spinning and parking, reveals the hidden spin within a Mutex, and explores why Go's runtime uses a "spinbit" design that allows only one goroutine to spin at a time.
You'll learn when spinning wins, when it's catastrophic, and why adaptive hybrid locks beat both pure approaches.
Main idea: A waiting goroutine can either spin (loop checking the lock, burning CPU) or park (yield to the scheduler, pay context switch overhead). Go's 'sync.Mutex' already spins internally (up to 4 iterations) before parking. The runtime uses the "spinbit" design: only ONE goroutine can spin at a time, preventing thundering herd problems.
Questions this talk answers:
When does spinning beat parking? Spinning wins when the critical section is shorter than a context switch (~1-2 microseconds). For sub-100ns critical sections on multi-core systems with low contention, spinning avoids scheduler overhead entirely. For anything longer, parking wins because you're just wasting cycles.
What does x86 PAUSE do? PAUSE is a hint that tells the CPU "I'm in a spin loop." It reduces power consumption, avoids memory order violations on speculative execution, and prevents the spinning core from flooding the memory bus with lock reads. Without PAUSE, spin loops can actually slow down the lock holder.
How does sync.Mutex spin? The runtime's 'runtime_canSpin' function checks: Are we on a multi-core machine? Have we spun fewer than 4 times? Is there an idle P available? Is the current goroutine's run queue empty? If all conditions are met, the goroutine spins briefly before parking.
What's the spinbit? A single bit in the mutex state that says "someone is already spinning." When set, other waiters go directly to sleep. This prevents N goroutines from all spinning simultaneously—only one burns CPU while others wait efficiently.
Why no SpinMutex in the standard library? Pure spinlocks are almost never the right choice in Go. Goroutines are cooperatively scheduled; a spinning goroutine can prevent the lock holder from running on the same P. The adaptive approach in 'sync.Mutex' handles the common cases correctly.
Attendees will understand when Mutex spins vs. parks, why pure spinlocks usually hurt Go programs, and the rare scenarios (sub-100ns critical sections, known multi-core, low contention) where custom spinning might help.
A possible beginner-level adaptation:
For a beginner audience, the talk would focus on the intuition behind spinning vs. parking rather than hardware details. I'd use the analogy throughout: spinning is pacing by the door waiting for a package, parking is taking a nap and asking to be woken up. The key insight is that both have costs: spinning wastes energy, and napping takes time to wake up. The talk would cover why sync.Mutex is almost always the right choice (it already handles the trade-off internally), demonstrate what happens when you write a naive spin loop (CPU spikes, other goroutines starve), and show the one-liner check to see if lock contention is your problem (go tool pprof mutex profile). Attendees would leave understanding why they shouldn't write their own spinlock and how to diagnose if sync.Mutex is a bottleneck in their application.
A possible advanced-level adaptation:
For an advanced audience, the talk would dive into the hardware and runtime implementation. We'd examine x86 PAUSE semantics (pipeline flush, memory-order implications, power reduction), how cache-coherence protocols (MESI) make naive spinning flood the memory bus, and the exact assembly Go generates for sync.Mutex.Lock. The talk would walk through runtime.lock2 and runtime_canSpin source code, explaining each heuristic: why 4 spin iterations, why check for idle Ps, why the run queue must be empty. We'd benchmark different spin strategies (exponential backoff, TTAS vs. TAS, ticket locks) and show when each wins. The spinbit design would get detailed treatment: how one bit prevents thundering herd, why it's set/cleared atomically with the lock state. Attendees would leave able to read and modify src/runtime/lock_futex.go and make informed decisions about custom synchronization primitives for extreme performance scenarios.
Green Tea GC: The Insight Behind Go's New Garbage Collector
Green Tea's insight is elegant: scan spans, not objects. But how do you actually implement that? What data structures track which objects are marked vs. scanned? Why does the ownership protocol use three states? And how did span-based scanning unlock SIMD optimizations that were impossible before?
This talk dissects Green Tea's implementation: the inline mark bits structure, the FIFO span queues, the ownership protocol that prevents duplicate work, and the AVX-512 SIMD kernels in Go 1.26 that use a cryptographic instruction (VGF2P8AFFINEQB) for bitmap expansion. I've read the actual runtime code and understand why each design decision was made.
Main idea: Green Tea required new data structures to batch objects by span. The 128-byte 'spanInlineMarkBits' structure stores mark/scan state inline at the end of each 8KB span. FIFO queues (not LIFO) let spans accumulate marks before scanning. An ownership protocol prevents duplicate work. And the regular data layout enabled SIMD acceleration in Go 1.26 using AVX-512 instructions originally designed for AES cryptography.
Questions this talk answers:
- Why 63 bytes for marks/scans? An 8KB span with 8-byte objects could hold ~1000 objects. But most size classes are larger. 63 bytes × 8 bits = 504 bits covers typical cases while keeping the structure at 128 bytes (two cache lines).
- Why FIFO queues instead of LIFO? LIFO (stack) would scan spans immediately after adding them—potentially with only one marked object. FIFO lets spans sit longer, accumulating more marks. When finally scanned, you process 10 objects in one cache-friendly pass instead of 10 separate passes.
- How does the ownership protocol work? Three states: unowned, one-mark, many-marks. When you discover a pointer, you atomically set its mark bit and try to acquire the span. If you get it, you enqueue the span. If someone else owns it, you just set the bit—they'll scan your object when they process the span. The one-mark state enables a fast path: skip bitset operations and scan the single object directly.
- How does SIMD help? Mark bits are 1 per object. Pointer scanning needs 1 bit per word (8 bytes). A 48-byte object needs its 1 mark bit expanded to 6 bits. The VGF2P8AFFINEQB instruction does 8×8 bit matrix multiplication—one instruction expands marks for an entire span. This instruction exists for AES; the Go team repurposed it.
- When does SIMD lose? Setup overhead matters. Dense spans (many marked objects) benefit from SIMD. Sparse spans (few marked objects) are faster with scalar iteration. The runtime tracks density and chooses dynamically.
Attendees will understand the data structures well enough to read 'mgcmark_greenteagc.go' themselves, know why each design decision was made (FIFO over LIFO, ownership states, dense vs. sparse paths), and see how architectural decisions cascade: span-based scanning enabled regular data layouts, which enabled SIMD, which the old object-centric GC couldn't use.
This talk is proposed af advanced level. Attendees should be comfortable with atomic operations, cache behavior, and reading Go runtime code. If needed, I'm open to adjusting the depth to benefit the conference.
Flight Recorder: Go's Black Box for Production
Debugging production latency is frustrating because you need to start tracing "before" the problem happens. You can't predict when a request will take 5 seconds instead of 50 milliseconds. By the time you notice, the interesting execution is gone.
Main idea: FlightRecorder continuously traces execution into a circular buffer with 1-2% overhead. When something interesting happens (slow request, error spike), you snapshot the buffer. The cause is already captured—no need to reproduce or predict when to start tracing.
Questions this talk answers:
Why can't pprof explain latency? pprof samples what's currently running on CPU. A goroutine blocked on a slow database call isn't running—it's invisible. pprof shows the CPU is idle. FlightRecorder captures blocking events, mutex contention, syscalls, and goroutine state changes—everything needed to understand where time went.
What's the overhead? 1-2% CPU overhead when recording. The runtime already collects most trace events; FlightRecorder just keeps them in a ring buffer rather than discarding them. Writes are batched and occur on dedicated goroutines to minimize latency impact.
What are MinAge and MaxBytes? MinAge says "try to keep at least this much history" (e.g., 30 seconds). MaxBytes says "but don't use more than this much memory" (e.g., 50MB). These are hints—the runtime balances them based on event rate. High-frequency events fill the buffer faster.
Why only one FlightRecorder per process? The trace infrastructure is process-global. Multiple recorders would need to coordinate buffer management and could interfere with each other. The limitation simplifies the implementation and avoids subtle bugs.
When should I snapshot? When request latency exceeds P99 threshold. When error rate spikes. When anomaly detection fires. Via a '/debug/snapshot' endpoint for manual investigation. The key insight: snapshot *after* detecting the problem, not before.
*Benefits for listeners: Attendees will know how to integrate FlightRecorder into production services, configure it appropriately (trading history length vs. memory), implement automatic snapshot triggers, and analyze traces with 'go tool trace'. The talk includes production patterns from real deployments.
This talk is currently proposed as intermediate level, but I'm open to adapting the depth if it benefits the conference.
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top