
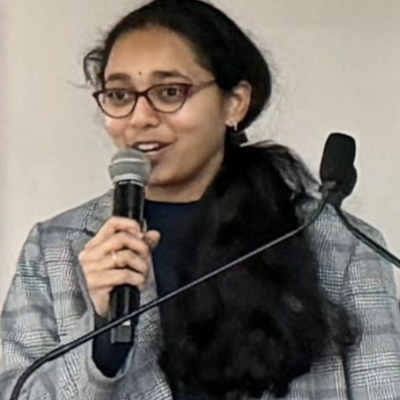
Anusha Kovi
Business Intelligence Engineer, Amazon
Seattle, Washington, United States
Actions
Anusha Kovi is a Business Intelligence Engineer at Amazon, where she builds and scales data platforms that power analytics, operational intelligence, and data-driven decision-making across large, distributed systems. She specializes in end-to-end data engineering—designing ETL pipelines and data models, orchestrating workflows with Apache Airflow and AWS, and delivering dashboards that turn raw data into clear insights that drive business outcomes. With 6+ years of experience, she is based in Washington, United States, and holds a Master's degree from Michigan Technological University.
Beyond her engineering role, Anusha is an IEEE-published author, a technical writer on DZone and Hackernoon, and a conference speaker whose work has been accepted at international research conferences and industry events. She’s passionate about making data engineering more accessible, advancing women in technology, and helping organizations build BI infrastructure that keeps pace with an AI-native world. She mentored 200+ students; a frequent judge and evaluator for student and industry innovation programs.
Links
Area of Expertise
Topics
Guardrails + Evals for NL-to-SQL Copilots: How to Ship Trustworthy Analytics Agents
NL-to-SQL copilots are easy to demo and hard to productionize: they hallucinate joins, leak restricted fields, and confidently return “correct-looking” numbers. This talk gives you a practical blueprint to ship an analytics copilot that your data team can actually trust—by combining policy enforcement (guardrails) with evaluation harnesses (evals) and failure-aware UX.
You’ll learn a concrete architecture for (1) permission-aware retrieval of semantic context (metrics, dimensions, join rules), (2) constrained generation that produces explainable SQL and bounded outputs, and (3) automated evals that catch regressions before your users do. You’ll leave with checklists, prompt and policy patterns, and an “MVP eval pack” you can run locally—no live internet required.
What you’ll walk away with
A reference architecture for NL-to-SQL copilots (semantic layer → policy checks → SQL generation → verification → answer)
A minimal eval suite (accuracy, safety, “metric integrity,” and regression gates)
Guardrail patterns for blocked columns, row filters, PII, and prompt injection
A playbook for “safe failure”: when to refuse, ask clarifying questions, or route to a human
From Demo to Durable: Trustworthy AI Analytics with Guardrails
AI analytics demos are easy. Production is where things break: leaked sensitive fields, wrong joins, “confident” hallucinated metrics, and silent policy bypasses. This talk is a practical playbook for turning a BI copilot/natural-language analytics assistant into something you can safely ship. We’ll cover the minimum guardrails that actually work in real teams: semantic-layer bound retrieval, policy-aware query construction, answer verification (SQL re-checks + metric validation), and lightweight evaluation harnesses that catch regressions before users do. You’ll see common failure modes, how attackers and normal users trigger them, and the simplest architecture patterns to prevent both data leaks and confidence leaks—without slowing down iteration.
Cost-Aware Data Engineering: Lessons from Building at Scale
The most uncomfortable meeting we ever sat in was with finance. They had pulled cloud spend data by team and wanted to understand why our data platform costs had tripled in eighteen months while the business metrics it supported had grown maybe thirty percent. We had good answers for some of it. For the rest, we had to admit we'd made engineering decisions that optimized for velocity and never thought about what they'd cost at the scale we eventually hit.
That meeting led to a cost audit that was, honestly, humbling. Full table scans on partitioned datasets running dozens of times a day. Glue jobs provisioned for peak load running constantly at ten percent utilization. Kinesis shards sitting idle because someone estimated high and nobody revisited it. S3 objects that should have moved to Glacier eighteen months ago still sitting in Standard storage because the lifecycle policy was on the roadmap and never made it to the sprint.
This talk isn't about being cheap. It's about being deliberate. At petabyte scale, the gap between an engineered cost posture and an accidental one is measured in hundreds of thousands of dollars annually. We'll share the cost attribution framework we built to actually understand where money was going—mapping specific pipeline components to specific spend across compute, storage, data transfer, and API calls, so engineers could see the financial impact of their architectural choices.
We'll cover the optimizations that moved the needle most: right-sizing EMR and Glue job configurations, S3 tiering and lifecycle automation, Kinesis shard management, and the Redshift Spectrum versus Athena decision tree that most teams get wrong because they're thinking about data volume instead of query frequency. We'll also talk about the behavioral patterns that quietly inflate costs and are almost never caught in code review.
Designing LLM APIs That Don't Hallucinate Your KPIs
We launched an LLM-powered analytics assistant that let business teams query their KPIs in plain English. Two weeks in, a VP flagged that revenue numbers didn't match the dashboard. Close — but not right. The model was generating SQL with a slightly different date grain than our canonical KPI definitions. No errors. No warnings. Just confidently wrong numbers in front of an executive. That's how LLM analytics tools fail: not obviously, but in ways that quietly destroy trust and kill adoption. The problem had nothing to do with the model. It was in how we designed the API layer connecting the LLM to our data systems — a mistake we've since seen replicated across many teams building similar tools. This session diagnoses the API-layer failures that cause LLM analytics to produce confidently incorrect outputs and presents the architecture patterns that prevent them. We cover KPI definition schemas explicit enough to eliminate LLM ambiguity, validation layers that catch semantic mismatches before results reach users, and fallback path design for queries the model shouldn't answer alone. The 60-minute format gives us time to go deep on the governance side: defining KPI ownership clearly enough for an LLM to use reliably, building feedback loops that surface hallucination patterns before they become trust problems, and structuring the collaboration between data engineering and the LLM application layer so the system stays trustworthy as both the data model and the underlying model evolve.
Building AI-Ready Data Foundations: The Pipeline Infrastructure Behind Reliable GenAI
Most GenAI failures aren't model problems — they're data pipeline problems in disguise. We spent months debugging a GenAI feature producing outputs our product team called confidently wrong. The model wasn't the issue. Two upstream systems were preprocessing the same field differently, and the resulting embeddings were subtly misaligned in ways that only surfaced under specific query patterns. The model was doing exactly what it was supposed to with inputs that were quietly broken. That experience reshaped how we think about GenAI reliability. The failure points teams blame on models are almost always upstream: inconsistent preprocessing, stale embeddings, retrieval pipelines built for analytics latency instead of inference latency, and absent data contracts between producers and consumers. In this session we define what AI-ready data actually means in practice — freshness SLAs, preprocessing consistency guarantees, validated embeddings with drift detection, and retrieval latency budgets that fit inside a user-facing inference window. We walk through a purpose-built AWS architecture: Glue Data Catalog for governed metadata, DynamoDB and ElastiCache for low-latency feature serving, Kinesis for real-time context injection, and Bedrock Knowledge Bases with pgvector on Aurora for RAG pipelines. We close with a practical pipeline audit checklist attendees can take back and apply to their own infrastructure the following week.
Agentic Data Pipelines: When AI Agents Manage Your ETL at Scale
A senior engineer on our team spent an entire Thursday chasing a timezone bug in a pipeline she hadn't touched in a year. Eight hours. One engineer. One bug. We'd had three variations of that same alert fire in the past month. That's the problem agentic data engineering actually solves — not AI hype, but wasted senior engineering time on work that follows patterns an agent can handle. This session shares what we built, where it worked, and where it didn't. We start with a taxonomy of ETL tasks genuinely suited to agent automation versus tasks that still need a human — getting that boundary wrong in either direction is costly. Automate too aggressively and subtle errors compound quietly. Stay too conservative and you've built an expensive system that still pages people for things it could handle itself. We walk through three production-ready patterns on AWS Bedrock, Step Functions, Glue, and Lambda: a data quality agent that triages anomalies and decides whether to auto-remediate or escalate; a schema evolution agent that detects breaking changes and drafts migration logic for engineer review; and an orchestration agent that adapts job scheduling to upstream data arrival and downstream SLAs. The 60-minute format gives us room to go deep on the reliability engineering most agentic talks skip — deterministic fallback paths, audit logging of agent decisions, cost controls that prevent runaway loops, and human-in-the-loop checkpoints that make the difference between a system your team trusts and one they're afraid to leave running overnight.
Real-Time Everything: Blending Streaming and Batch on a Modern AWS Stack
Most data teams end up running streaming and batch side by side — not by design, but because batch never fully disappears. The fraud pipeline needs sub-second latency. The financial report still runs overnight. And nobody warned you that adding streaming to an existing batch platform means owning two systems, two operational models, and twice the on-call surface area. This session gives you the decision framework and architecture to make them coexist. We start with a workload classification model for deciding when real-time is worth the complexity — over-engineering toward streaming is one of the most expensive mistakes a data platform team makes, and this framework helps you avoid it before the infrastructure is already in place. From there we walk through the hybrid AWS architecture: Kinesis Data Streams and MSK for ingestion, Lambda and Managed Flink for real-time processing, Glue and Step Functions for batch orchestration, and Apache Iceberg on S3 as the unified storage layer that keeps both worlds consistent. The 60-minute format lets us go deep on the operational problems most talks skip: exactly-once semantics across paradigm boundaries, late-arriving data that silently corrupts aggregates, schema evolution that breaks consumers downstream, and unified observability across streaming and batch. Every pattern is drawn from production systems processing petabytes of data.
Cost-Aware Data Engineering: Lessons from Building at Scale on AWS
Our data platform costs tripled in eighteen months while business value grew thirty percent. Finance noticed. The audit that followed was humbling: full table scans on partitioned datasets running dozens of times daily, Glue jobs provisioned for peak load running at ten percent utilization, Kinesis shards sitting idle since the original estimate, and S3 objects in Standard storage because lifecycle policies never made it to the sprint. This session is a practical guide to cost-aware AWS data engineering drawn from that audit. We start with a cost attribution framework that maps pipeline components to specific spend categories — compute, storage, data transfer, API calls — so engineers can see the financial impact of their architectural choices before they compound. The bulk of the session covers the optimizations that moved the needle most: right-sizing EMR and Glue job configurations, S3 lifecycle tiering automation, Kinesis shard management, and the Redshift vs. Athena decision tree most teams get wrong because they evaluate data volume instead of query frequency. The 60-minute format gives us time to go deep on the Spark join and partitioning anti-patterns that quietly inflate costs in ways code review never catches, and to close with a governance model — cost tagging, budget alerting, ownership assignment — that keeps spend visible and accountable before it becomes a difficult conversation with leadership.
Anusha Kovi
Business Intelligence Engineer, Amazon
Seattle, Washington, United States
Links
Actions
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top