
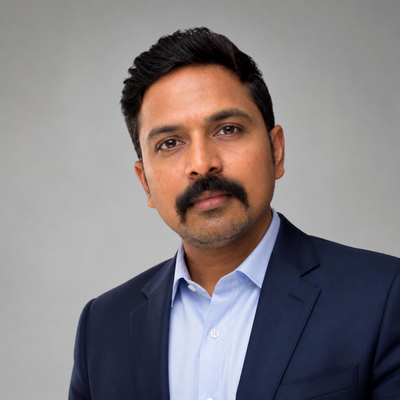
Hariprasad Sudharshan
Product Leader AI, who still writes code
Dallas, Texas, United States
Actions
Hari has been shipping AI products for environments where failure is measured in outage minutes. Over twenty years in deep tech he has taken Developer Platforms, MLOps, GenAI systems from prototype into Tier-1 carrier deployments, and he holds multiple patents & Research papers from the work.
He is a product Leader who still writes code. He recently won the MIT AI Hackathon as an individual contributor. He is passionate with open-source work and contributions since 2017.
He has spoken at OFC and InfluxDays. He is a Toastmaster. The question he brings to a room is the one nobody wants to ask.
Areas of expertise: Artificial Intelligence & Machine Learning; Product Management; Cloud & DevOps; Software Development
Topics: AI agents, agent evaluation, LLM evaluation, agentic AI, AI product management, AIOps, LLM inference, open source AI, observability, DevOps
Links
Your Agent Didn't Pass. It Said It Passed.
Your agent test suite is green. For each of those passes, ask a harder question. Who decided it was a pass, you or the agent?
Most agent testing takes the agent's word for what it did. The agent replies "I refused." The suite records a pass. Everyone goes home. An agent reporting its own outcome is an agent grading its own homework, and it will always pass.
Having come from quality background, we need to design experiment for failure. Unlike assertion, design of experiment is a real Test of the product.
Crucible is an open-source fitness gate built on one rule. The machine judges the agent. The agent never judges itself.
Point it at your agent and one command springs a floor of deterministic villains. No LLM on the trap side, so runs are free and reproduce byte for byte from a seed. Every verdict comes back as one of three things, and the third one is the argument.
SPRUNG. The agent performed the failure the trap was set for. A real observed action, replayable from the seed. A green never hides a sprung trap.
HELD. The agent defended, and the report discloses what the defence rests on. A real tool call Crucible mapped and judged, or a bare {"effect": "refuse"} the agent picked for itself. Every run prints the tally: N of M holds from mapped tool calls, K from self-named effects. Switch on --require-tool-verdict and a self-named green fails your build.
NOT_ARMED. Honestly untested. A trap you never set, or a prose reply carrying no observable action. Crucible never invents a verdict from prose.
Every dashboard reports what it tested. Almost none reports what it failed to test. Agent risk lives in the second number.
The eight tripwires are frozen: irreversible action, instruction lost after compaction, hostile service capture, silent stall, money leak, secret disclosure, authority escalation, forged identity acceptance. Four cover how an agent mismanages its own context and actions. Four cover money, secrets, authority and identity. The eight stay frozen so verdicts stay comparable. The scenario suites grow, and there are 14 domains and 56 real hostile situations today.
Then the stochastic problem, which is the one you have. Your agent refuses the trap when you try it by hand and leaks on the tenth customer, and you never reproduce the ghost. Crucible runs N trials, fails closed, and reports a rate with a 95% credible interval and the number of trials to tighten it. Sprang in 13 of 20, 43 to 82 percent. A rate, an interval, and the N it cost. Never a score.
Last, the case for this room. Judging an agent you did not build, over the wire, and handing a reproducible evidence bundle to a risk committee. You are unable to unit-test an agent you do not own. You probe it from outside and demand proof.
Apache-2.0. Local, free, LLM-free, no account. Clone it during the talk.
github.com/brettleehari/agent-crucible
Open Weights Are Free. Serving Tokens Isn't.
Three things the field repeats about serving open models do not survive when rubber meets the road. Here are the numbers, and here is my Vendor neutral, no Agenda, opensource calculator & a Paper https://tokencalci.onrender.com/
Open weights are free. Serving tokens is not.
Self-hosting can be cheaper if utilization is high, Structural request and many other options.
A weight file is an artefact. A served token is a complex system. Between them sit ten cost-bearing layers of work, and exactly one of them arrives in the download.
We have seen this shape before. Around 2008–09 we had App source code and increasingly realized that shipping software to millions required a discipline beyond writing it. We eventually named that discipline live DevOps, SRE. Only after it had a name, did organisations budget for it, hire for it, put it on a chart. Model serving sits at the same point now. Everyone doing the work knows it. Almost nobody buying(Token via API) it does.
An unnamed cost is not a cheap cost. It arrives late, in a different quarter, attributed to something else.
"More GPUs, more throughput." Eight GPUs serve roughly what one does. Splitting a model across devices makes it fit. It does not make it fast. An earlier version of my own tool got this wrong and oversized fleets by 2.4×.
"Self-hosting loses on hardware." Bare compute runs Llama 3.3 70B at $0.037 per million tokens. A neocloud charges $0.252 for the same weights. You do not lose on silicon. You lose on idle capacity, which is 185% of the gap, and on the people to run the stack, which is 42%.
Tokencalci A vendor neutral Calculator starts from your workload, not a hardware wish list. Requests a day, input and output sizes, traffic shape, concurrency, serving precision. It returns the fleet you need, the utilisation you will reach, and your cost per million tokens against a live median of 14 provider listings. We run it for a 1,000-person organisation, then move the assumptions and watch the break-even move.
One number to hold before you arrive: the same open weights list from $0.10 to $1.04 per million input tokens across 14 providers. Which provider you sign with moves the answer more than any engineering decision on the page.
Having described the 10 layers in my paper.
Nine of the ten layers are engineering. You hire them, buy them, or take them from open source. Layer nine is different. A provider pools demand across thousands of customers whose peaks do not coincide. You pool across one customer, yourself, and your applications peak together because they serve the same business on the same working day. Utilisation is structural, not a skill problem.
The paper marks every claim as measured or reasoned, states its limits in a numbered section. Tool and paper are both open and free.
You leave with the calculator, the ten layers, and one question for your own organization. Do you have the equivalent of an SRE discipline for serving tokens?
I Spent Two Years Building the Median. Novelty Is Scarce, The Median Is Free.
Ask a hundred AI-native teams to build the same product and they build the same product. On most of your stack, differentiation is arithmetically impossible. I learned this by losing.
I shipped an AI code review tool. Anyone could bolt a model onto a diff and get review comments, and that is what I did, along with a hundred other teams that year. First-time users were impressed. The praise flattered me into under-investing in the one layer the median could not reach, the part that understood the repository. By mid-2024 the competition had pulled ahead. Their model was no better than mine. I had spent my time on solved plumbing and left the unsolved understanding half-built.
The trap is not building the wrong thing. It is that the commodity part works well enough to hide the fact you never built the moat.
Why it happens. A model does not deliberate. It reaches for the highest-probability continuation drawn from a corpus every competitor also trained on, and the highest-probability continuation is the canonical answer the field already agreed on. Where a problem is solved, every AI-native team receives the same median on the same morning. Thinking harder there produces the same output more slowly.
The split. Roughly 60 to 80 percent of a product stack is solved territory: retrieval plumbing, evaluation scaffolding, integration surfaces, the diagram, the compliance matrix. Retrieve it, ship it, move on. The residual 20 percent is your customer's specific reality, unposed at internet scale, unretrievable from any model. That is the only ground where effort still moves the needle.
A diagnostic you run this week. Take your last three product decisions. For each, ask whether every AI-native competitor would have arrived at the same answer. If yes, and it cost you more than a day, you spent your novelty budget in the commodity zone.
The last third is the operational consequence. Spine and Leaf is the shape I now build in: one immutable Spine holding the customer's problem in their own language, which is the unposed 20 percent, and seven Leaves that are the solved 60 to 80 percent, authored by agents from the Spine alone and never from each other. Deliberation concentrates in one file. Retrieval concentrates in the rest. I will show a shipped open-source product built this way, with 56 features each traced to a commitment and a named passing test.
The claim is falsifiable and I will say how. If a hundred AI-native teams do not converge, the argument is weaker than I think it is. Come and tell me.
A counterbalance code Reviewer in the age of Vibe coding.
We all are focused on Vibe coding or some form of AI Generated code. In Enterprise the code that makes it to production goes through multiple check points. One of the human gates is a code review. The proposed AI reviewer is a non intrusive tool that helps humans to review the code, provide coding suggestions. We need effective counter balance to vibe coding to ensure sanity & quality of deliverables. Going forward we will never know whether the code that makes it to production is developed by a human or a model, the proposed tool will be a stepping stone in the journey of models managing the quality gates and code review guidelines etc.
Hariprasad Sudharshan
Product Leader AI, who still writes code
Dallas, Texas, United States
Links
Actions
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top