
Session
Why AI Fails Before the Model
Everyone is talking about models, agents, and copilots.
Yet many AI initiatives struggle long before a prompt is ever written or a model is ever deployed.
The reality is that AI systems inherit the strengths—and weaknesses—of the data ecosystems beneath them. Fragmented data, undocumented business rules, inconsistent metadata, disconnected systems, and poor feedback mechanisms often become the true barriers to AI success.
While leading large-scale modernization efforts involving more than 100 million records across legacy databases, documents, spreadsheets, and operational systems, I discovered that the hardest AI challenges were not AI challenges at all. They were data challenges.
In this session, I'll share practical lessons from transforming decades-old systems into modern, AI-ready platforms. We'll explore the hidden engineering work that happens before machine learning, retrieval-augmented generation (RAG), agents, and decision intelligence can deliver value. Attendees will learn how to identify foundational risks, reconstruct critical context from legacy systems, establish trustworthy data pipelines, and design feedback mechanisms that enable AI systems to improve over time.
If you're building AI applications, platforms, or agents, this session will help you understand why successful AI starts long before the model—and how to build the foundation that allows AI to succeed.
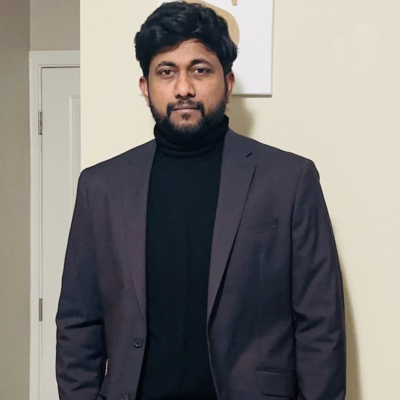
Srinivasa Rao M
Data Engineer & Founder @DeepTrics
Meridian, Idaho, United States
Links
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top