
Session
Evidential Ceilings: What AI Red-Team Evaluations Can and Cannot Prove
LLM safety benchmark and red-team results are increasingly treated used to make deployment safety claims and inform regulatory decisions. But did we ever examine the inferential leap from a finite assessment to a safety claim? Drawing on her preprint, Bandana introduces the “evidential ceiling”: a calculable limit on how much any benchmark can shift belief about rare harms. Above a computable harm rate, modest benchmarks can certify a safety category; below it, no feasible benchmark provides adequate evidence. Attendees leave with a closed-form way to decide, before testing, whether an evaluation can actually support the safety claim they need, and how to make more robust and trustworthy claims about the results of LLM safety evaluations.
Based on arXiv cs.AI https://arxiv.org/abs/2607.21735
Audience Level: Intermediate (Cybersecurity teams, AI-safety teams, ML leadership, policymakers, and evaluation/red-team practitioners)
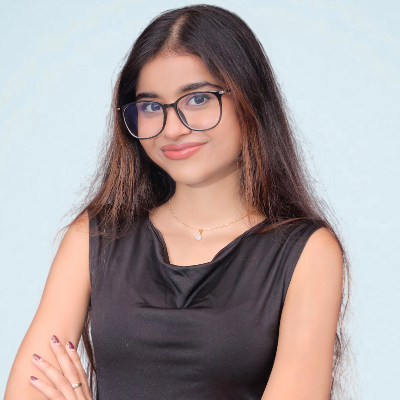
Bandana Kaur
Offensive AI & Application Security Researcher
Delhi, India
Links
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top