
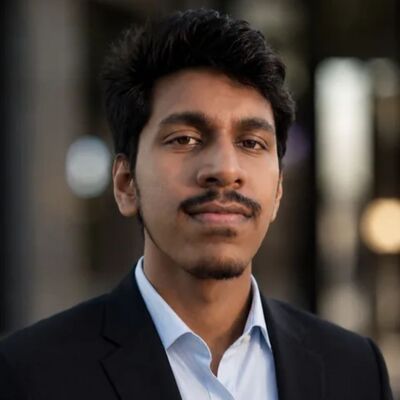
Samir Sengupta
AI/ML ENGINEER, BUILDING AGI
New City, New York, United States
Actions
Samir Sengupta is an AI/ML engineer in New York who builds production LLM, RAG and multi-agent systems, and the infrastructure that keeps them reliable once the demo is over.
Over 3+ years at SynRadar and Neural Thread he has shipped Kafka pipelines processing ~500K events a day, ML services on Kubernetes at sub-100ms p50 latency, and NLP ticket routing that cut manual triage by about 40%. He is the founder of SyGentAI, which builds agent systems where agents propose, humans approve and every action is logged.
He runs his own fleet of websites, unattended LLM publishing pipelines and agents that are built and operated largely by coding agents, and he writes about what breaks. His open work includes Wayne, an AI coding harness for VS Code; PrometheusAI, an offline LLM assistant for Android; tokenash, a local-first context compressor; and a TechRxiv preprint on long-context LLMs for edge devices.
In 2026 he spoke at KCD New York, Apache Beam Summit NYC and Blockchain Week UNGA Edition. He holds an M.S. in Data Science from Saint Peter's University.
samcodeman.com · github.com/SamirSengupta · linkedin.com/in/samirsengupta
Area of Expertise
Topics
From RAG to Agents: Building Real-Time AI Infrastructure for Web3
As AI moves from chatbots to autonomous agents, the hardest challenge isn't getting an LLM to reason. It's building the infrastructure that allows agents to reliably understand live data, use external tools, and take actions in production.
In this talk, I'll walk through how I approach building production-grade AI systems for real-time Web3 and financial applications, combining LLMs, RAG, agentic workflows, vector search, and scalable inference infrastructure.
We'll cover:
How to build RAG systems that continuously retrieve and reason over real-time blockchain and financial data
Designing agentic workflows where LLMs can use tools, query external systems, and interact with Web3 applications
Handling the latency, throughput, and cost challenges of running LLM inference in real-time systems using vLLM, batching, quantization, and GPU optimization
Architecting the infrastructure layer across Kubernetes and cloud AI platforms for scalable agent deployment
Preventing hallucinations and stale information when AI systems operate on rapidly changing transactional and financial data
Building observability, evaluation, and reliability mechanisms for autonomous AI workflows
Real-world architecture patterns for applications such as fraud detection, market intelligence, compliance, risk analysis, and intelligent financial automation
This isn't a theoretical discussion about AI agents. The focus is on the engineering required to make these systems reliable, scalable, and production-ready.
Attendees will leave with concrete architecture patterns for combining real-time data, RAG, LLM inference, and autonomous agents to build the next generation of AI-native Web3 applications.
Real-Time AI Pipelines at Scale: Embedding LLMs into Apache Beam for Live Inference
As AI moves from experimentation to production, the hardest challenge isn't building a model. It's getting it to run reliably on live data at scale. In this talk, I'll walk through how I architected production-grade pipelines that embed LLMs and RAG systems directly into Apache Beam, enabling real-time inference on high-velocity data streams.
We'll cover:
How to integrate HuggingFace and vLLM models into Beam transforms for low-latency inference
Designing a RAG pipeline inside Beam using vector databases (Pinecone, FAISS) for semantic search on streaming data
Handling the cost and throughput challenges of running LLMs in a pipeline (quantization, batching, GPU optimization)
Deploying the full stack on AWS Bedrock + SageMaker with Kubernetes orchestration
Real benchmark results: how we cut inference costs by 50% while improving reasoning accuracy by 35%
This isn't a toy demo. It's a battle-tested architecture handling 10M+ daily events with 99.9% uptime. Attendees will leave with concrete patterns they can apply to fraud detection, anomaly detection, semantic search, and personalized recommendation systems.
Scaling Production RAG Systems with Kubernetes
Deploying LLM applications at scale requires reliable cloud native infrastructure. This talk explores how to run production RAG pipelines using Kubernetes, covering vector search services, scalable inference with vLLM, and distributed embedding pipelines. We will discuss observability, cost optimization, and autoscaling strategies for real world AI workloads running in containerized environments.
UN Blockchain Week Sessionize Event
Beam Summit 2026 Sessionize Event
KCD New York 2026 Sessionize Event
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top