
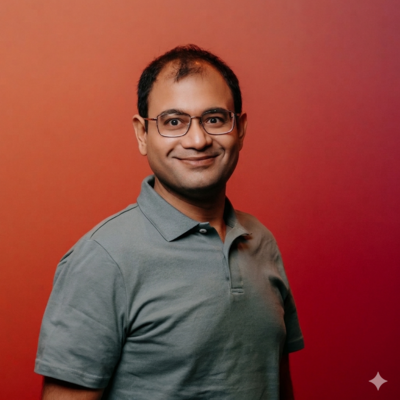
Shuva Jyoti Kar
Palo Alto Networks, Sr Principal Engineer, Network R&D
Bengaluru, India
Actions
Shuva is a Senior Principal Engineer at Palo Alto Networks architecting secure enterprise AI platforms. He is authoring two upcoming books: Engineering the Data Agent Control Plane (O'Reilly) and Agent Skills in Action (Manning). An open-source contributor and former OpenDaylight committer, his work bridges experimental AI and 'Day 2' production reality. He is a Confluent Community Catalyst Nominate for 2026 and a speaker at OpenSource Summit, GDG Events, IEEE conferences on scalable, zero-trust data architectures.
Badges
Area of Expertise
Topics
Architecting Autonomous Systems in Cloud-Native Environments.
The era of static, chat-based AI is evolving into the age of "Agentic AI"—autonomous systems that actively reason, execute multi-step workflows, and manipulate external tools to achieve complex goals. However, moving these agents from a local Python notebook to a scalable, secure enterprise environment presents unique infrastructure challenges. Agents are often bursty, highly state-dependent, and require long-running execution times that defy traditional request-response paradigms.
In this session, we will deep-dive into why serverless containers have emerged as a premier substrate for hosting these autonomous workloads. Moving beyond basic deployment tutorials, we will explore the architectural patterns necessary to build robust, production-ready agentic systems. Attendees will learn how to leverage unique concurrency models to handle the "waiting patterns" of agents—such as awaiting external tool outputs or human-in-the-loop feedback—without incurring massive idle costs. Finally, we will address the critical security boundaries required when giving AI agents the keys to your enterprise data and APIs.
The Platform Habba: Bengaluru Tech Week 2026
Architecting Self-Contained Data Agents on AWS Fargate
Enterprise AI is moving beyond simple chatbots into autonomous data agents, but orchestrating their interactions with massive, distributed databases introduces a critical flaw: the latency bottleneck. Traditional hub-and-spoke architectures rely on continuous network round-trips to centralized data warehouses. The network latency interrupts the agentic reasoning loop, turning sub-second thought processes into tasks that take minutes. What if the agent and the database lived inside the same immutable container?
Here we will explore the architecture of "Self-Contained Data Agents." By combining an agentic orchestration layer with an embedded OLAP engine (chDB) inside a single Docker container, we can eliminate network hops and achieve sub-second, direct-memory data access.
We will show how to seamlessly map this architecture to AWS, utilizing AWS Fargate for true scale-to-zero serverless compute, Amazon S3 for "fetch-on-boot" state persistence, and Amazon CloudWatch for observability.
AWS Community Day Bengaluru 2026
Building a Self-Service Platform for Stateful AI Agents
AI agents are moving from prototypes into production, and platform teams are increasingly asked to provide a “paved road” for deploying them safely. But agentic workloads don’t fit neatly into traditional stateless service templates: they pull in embeddings and retrieval context, call tools, stream responses, and require repeatable execution across environments—often leading to one-off deployments and operational inconsistency.
This talk presents a platform engineering "path” for agentic workloads using a pattern we call self-contained data agents: a standardized, containerized unit that packages the agent runtime, tool contracts, and data-adjacent execution model behind a clear service boundary. We’ll show how Knative enables a consistent developer experience—request-driven deployment, scale-to-zero, revision-based rollouts, and session management—while keeping the platform portable and Kubernetes-native.
KubeCon + CloudNativeCon India 2026, Mumbai
Engineering Enterprise Serverless Data Agents
Cloud-native data processing is evolving from static pipelines to autonomous "Data Agents" powered by in-flight LLMs. However, integrating high-throughput event streaming (Kafka) with high-latency AI compute creates massive distributed systems friction. Traditional stream processors choke on LLM latency, causing unmanageable consumer lag and cascading failures. This talk explores a novel pattern to solve this impedance mismatch: decoupling throughput from reasoning via event-driven serverless architectures (Knative). We demonstrate building "Sense and Act" data agents that leverage container concurrency to natively absorb AI processing variance. We also introduce "Localized Reflexes"—embedding in-process query engines (chDB) directly into serverless pods. This creates self-contained edge nodes that bypass expensive LLM network hops entirely. Finally, we dissect stateless, stateful, and edge-agent topologies to operationalize reliable agentic workflows on Kubernetes.
The AI Infrastructure Meetup: BLR. vCluster+Cloudera
MCP: From Protocol to Production
The Model Context Protocol (MCP) is the open standard revolutionizing how Large Language Models (LLMs) connect with external tools and data.
This session will take you on a journey from the core theory to a secure, scalable deployment. We'll start with the MCP fundamentals—exploring its client-server architecture, the role of tools, resources, and prompts, and the JSON-RPC-based communication details.
Next, we'll dive into the security challenges inherent in this powerful design, covering critical risks like Prompt Injection, Tool Poisoning, and credential management, and discussing mitigation best practices.
Finally, we'll demonstrate how to go from development to a robust, production-ready server by leveraging Cloud Run. Learn how the serverless execution model simplifies deployment, offers built-in security controls, and provides auto-scaling for your next-generation AI agents.
GDG Devfest Nashik 2025
Mind the Autonomy
This session offers a critical and timely exploration into the evolving landscape of cybersecurity, directly confronting the seismic shift brought about by Agentic AI. As artificial intelligence transcends static, reactive systems to become truly autonomous, goal-driven entities, our established security paradigms—especially foundational threat modeling practices—are being rendered dangerously obsolete.
The core premise is that traditional threat modeling, built on assumptions of predictable systems and human control, is fundamentally unprepared for these self-governing AI entities. We will unveil the profound "autonomy gap" that exists between current security practices and Agentic AI's emergent capabilities. This gap manifests in several critical areas:
• Unpredictable Decision-Making
• Dynamic and Evolving Attack Surfaces
• Expanded Attack Vectors via Tool Use
• Goal Misalignment and Drift
• Challenges in Explainability and Auditability
• The Overwhelmed Human-in-the-Loop
GDG Ahmedabad DevFest 2025
Taming the Chaos: How Not to build Distributed AI Application(s)
Designing and deploying distributed AI applications is an exciting endeavor, often accompanied by unexpected challenges and lessons that shape how we design complex distributed systems. In this session, I will share hard-earned insights gained from building a distributed AI application, focusing on key failure points and how to address them effectively. From security vulnerabilities to AI hallucinations, real-time failures, and the critical need for keeping humans in the loop, this presentation explores the pitfalls and solutions that every AI developer and system architect should understand.
Security in distributed AI systems is a constant concern, with sensitive data and communication channels vulnerable to breaches and adversarial attacks. I will discuss real-world examples of how security failures can occur and share strategies for building robust, secure systems. Additionally, I'll delve into the phenomenon of AI hallucinations-when models generate plausible but incorrect outputs-and explain how these errors propagate in a distributed environment, creating downstream issues.
Real-time failures are another key challenge, where latency, synchronization issues, and system reliability can significantly impact performance. Drawing from my experience, I'll highlight best practices for optimizing real-time AI systems to maintain efficiency and consistency.
Finally, I'll emphasize the importance of keeping humans in the loop in decision-making processes. While AI systems are powerful, they are not infallible, and removing human oversight can lead to ethical, operational, and trust-related failures. I'll provide actionable tips for designing workflows that combine the strengths of human judgment with AI capabilities.
By the end of this session, attendees will walk away with a clearer understanding of the challenges involved in distributed AI systems and practical strategies to mitigate them, ensuring more secure, reliable, and human-centered AI applications.
Cloud Community Days Kolkata 2025
Zero-Trust Execution: Sandboxing MCP Data Agents with WebAssembly
The Model Context Protocol (MCP) standardizes context retrieval and tool execution, but granting LLMs access to dynamic execution environments introduces critical runtime vulnerabilities. Traditional containerization (e.g., Docker/containerd) introduces unacceptable latency overhead for sub-second agentic loops, while static IAM/RBAC models fundamentally fail to constrain non-deterministic generated code.
This technical session details the architectural implementation of embedding a WebAssembly (WASM) runtime within an MCP server to enforce a strict, capability-based execution boundary. We will deconstruct how to compile MCP tools to WASM modules and utilize the WebAssembly System Interface (WASI) to ensure that any logic invoked by an LLM is isolated from the host operating system.
MCP Dev Summit Mumbai 2026
Beyond Throughput: Production Lessons from Running Write-Heavy Valkey Clusters
Synthetic benchmarks measure how fast Valkey can run. Production measures how long it remains predictable, and those are different questions.
Under sustained, high-volume write ingestion, as in a production-scale CDC pipeline, raw throughput is rarely the limiting factor. Instead, clusters become unstable when replication falls behind during resharding, memory amplification exhausts available headroom before eviction recovers capacity, or failover triggers large-scale reconnect storms.
These failure modes rarely appear in benchmark reports, but they're often responsible for production outages.
Using a production-scale CDC workload as the reference system, we'll investigate how Valkey behaves under sustained write load, exploring:
* Why is replication an early warning signal of cluster instability?
* How do resharding, replica promotion, and failover interact under write load?
* Why adding replicas doesn't always improve resilience.
* The operational signals and metrics that reveal instability before users do.
You'll leave with practical heuristics for capacity planning, shard sizing, observability, failover testing, and operating Valkey clusters under sustained write pressure.
ValkeyConf 2026, Prague, Czechia
Beyond Vibe-Testing: Engineering Deterministic Agent Skills
The AI ecosystem suffers from a critical engineering immaturity: deploying stochastic models via manual "vibe checks." Operating autonomous agents at enterprise scale requires abandoning ad-hoc observation for strict, distributed systems rigor. This session introduces a deterministic, CI/CD-native evaluation architecture for Agent Skills, shifting from indeterministic to reliable software execution.
By adhering to the formalized capability standards defined by agentskills.io, we will deconstruct the transition from subjective testing to hermetic, code-driven audits. Attendees will learn to engineer scenario matrices that enforce strict cognitive boundaries via negative testing—guaranteeing agents safely reject out-of-scope triggers. We will demonstrate isolating execution within sandboxed environments to capture pristine telemetry: deterministic tool-call structures, system exit codes, and exact token utilization.
Crucially, we address the anti-pattern of relying on "LLM-as-a-judge" for critical path assertions. Instead, we architect a framework grading system invariants via AST parsing and JSON Schema enforcement to achieve instantaneous, hallucination-immune evaluation.
AGNTCon + MCPCon Europe 2026, Amsterdam, Netherlands
Building a Self-Service Platform for Stateful AI Agents
AI agents are moving from prototypes into production, and platform teams are increasingly asked to provide a “paved road” for deploying them safely. But agentic workloads don’t fit neatly into traditional stateless service templates: they pull in embeddings and retrieval context, call tools, stream responses, and require repeatable execution across environments—often leading to one-off deployments and operational inconsistency.
This talk presents a platform engineering "path” for agentic workloads using a pattern we call self-contained data agents: a standardized, containerized unit that packages the agent runtime, tool contracts, and data-adjacent execution model behind a clear service boundary. We’ll show how Knative enables a consistent developer experience—request-driven deployment, scale-to-zero, revision-based rollouts, and session management—while keeping the platform portable and Kubernetes-native.
KCD Washington DC 2026
MCP: From Protocol to Production — An Architect's Guide to Secure Deployments
The Model Context Protocol (MCP) standardizes how AI models connect to enterprise data, but migrating from a local developer environment to mission-critical infrastructure fundamentally expands the enterprise attack surface. Without rigorous architectural boundaries, an MCP server transitions from a context-provider into a vector for network-level and execution-level exploits.
This session serves as the definitive architect's guide to the MCP lifecycle. We will cut through the AI hype to deconstruct the protocol’s architecture, mapping the exact threat models and operational realities of "Day 2" production environments.
Rather than theoretical use cases, this talk focuses on the mechanical realities of the protocol. We will explore how autonomous reasoning loops interact with transport layers, unpack recent SDK vulnerabilities, and define the architectural patterns required to operate multi-tenant data agents securely.
Global AI Community, MCP Community Connect - Bengaluru
Overcoming Temporal Blindness: Serverless Cross-Temporal Reasoning with Neo4j and LangChain
Standard GraphRAG architectures excel at semantic retrieval but frequently fall into the "stale-data trap," prioritizing keyword similarity over chronological validity. In high-velocity, state-dependent domains like cybersecurity, this temporal blindness leads to catastrophic reasoning failures—such as an agent failing to correlate a live threat with an obsolete security configuration change from months prior.
This session introduces s-TRAG (scalable Temporal Retrieval Augmented Generation), a serverless framework that integrates Temporal Knowledge Graphs (TKGs) in Neo4j with an ephemeral agentic orchestration layer on Google Cloud Run. We will demonstrate how to decouple temporal reasoning from execution to eliminate the overhead of persistent infrastructure while achieving an 87.4% reduction in operational costs, a 40.6% gain in Temporal QA Accuracy, and an 82% reduction in factual hallucinations.
Attendees will walk through the mathematical optimisation of a Temporal Alignment Score (TAS), the implementation of a ReAct-driven graph traversal loop, and real-world optimisations that deliver a 53.2% reduction in P99 latency by leveraging persistent connection pooling across serverless container instances.
NODES 2026
Poisoning the Well: Security Lessons from Vulnerability Research in Telemetry Pipelines
Observability pipelines are the nervous system of modern cloud-native infrastructure. However, the streaming platforms, vector databases, and log aggregators powering these environments have become high-value targets for threat actors. This session presents a real-world case study centered on security research that uncovered and reported critical vulnerabilities across enterprise streaming architectures and API infrastructures. The presentation explores how systemic architectural misconfigurations can expose data pipelines to severe exploits like DNS rebinding, Server-Side Request Forgery (SSRF), and malicious payload manipulation.
Moving beyond the exploits, the case study provides a detailed account of the remediation and hardening process. Attendees will learn practical strategies for integrating robust DevSecOps practices directly into their observability deployments. The speaker outlines how to enforce secure network boundaries around centralized data stores and utilize open-source tools like Prometheus and Fluentd to actively monitor the pipeline's health, ensuring the integrity of the telemetry stream against malicious exploitation.
Observability Summit Europe 2026, Prague, Czechia
Runtime Isolation for AI Agents: Sandboxing Tool Execution on Kubernetes
AI agents break a core assumption of platform engineering: that what runs in production is fixed at deploy time. An agent's tool calls are shaped by model output at runtime, so the same Pod can behave differently, and dangerously every time it runs. Give it a shell or an API token, and failure shifts to runaway execution and privilege misuse.
Tooling is evolving to meet this threat. The agent-sandbox project (Kubernetes SIG Apps) and isolation runtimes like gVisor and Kata are being wired into agent workflows. But this introduces a tradeoff: waiting seconds for a secure Pod to spin up breaks the agent's reasoning loop.
This talk maps four-layered patterns: sandboxed execution, workspace volumes, network policy, and runtime observability. We'll examine what Pod Security Admission and seccomp give you for free, and where agent-sandbox fills the gaps - using SandboxWarmPool to eliminate cold-starts and SandboxClaim to vend environments.
Crucially, we'll delineate Execution Isolation (preventing kernel escapes) from Behavioural Isolation (preventing data exfiltration), leaving you with a practical framework for running agents without treating every tool call as an incident.
Open Source Summit + Embedded Linux Conference Europe 2026
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top