
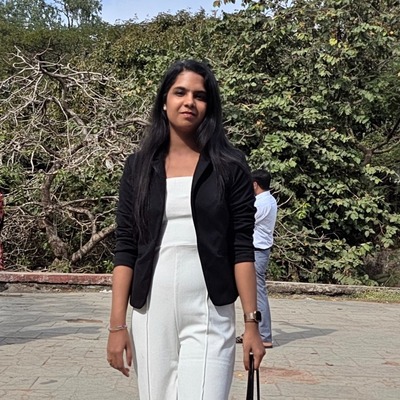
Snigdha Kashyap
Contributing to #Tech as SDE-2 @ExpediaGroup
Gurugram, India
Actions
A Software Development Engineer with over three years of experience specialising in software development (majorly backend) and cloud technology. I have contributed to robust, scalable systems across various tech stacks in previous roles at Freecharge Payments and Airtel Payments Bank. With a zeal for building efficient, user-centric applications. A problem-solver and avid technologist.
Area of Expertise
Topics
The Dual-Write Dilemma: Solving Distributed Consistency in High-Concurrency Microservices
In high-throughput microservices and distributed transaction environments, basic retry loops and naive backoff strategies frequently turn temporary network hiccups into cascading outages and thundering herds. Ensuring high availability and sub-50ms tail latencies requires proactive failure containment, deterministic state handling, and intelligent traffic shedding.
In this architecture-focused session, we deconstruct battle-tested engineering patterns for building fault-tolerant backend systems:
Blast-Radius Containment: Implementing bulkhead patterns and adaptive circuit breakers that isolate partial degradation without knocking out upstream services.
True Idempotency at Scale: Enforcing end-to-end consistency across async message brokers and distributed data stores using transactional outbox patterns, Redis locks, and deduplication tokens.
Taming Distributed State: Practical strategies for decoupling monolithic transactions into event-driven Sagas, automated dead-letter queue (DLQ) triage, and zero-data-loss reconciliations.
Database & Socket Preservation: Mitigating connection starvation and socket exhaustion through connection pooling optimizations, backpressure orchestration, and read/write splitting.
Key Takeaways for Attendees:
Concrete blueprints to implement transactional outbox and saga patterns for state consistency across decoupled services.
Practical defensive techniques to configure adaptive rate limiters and circuit breakers that safely shed load during peak surges.
Observability patterns to trace tail latency regressions (p95/p99) and socket pool starvation before incidents manifest in production.
Defeating the Retry Storm: Designing Idempotent Microservices on Google Cloud
Problem: In distributed systems, network calls fail, timeouts happen, and upstream services inevitably hit retry. If our backend services aren't designed to handle this, a simple network blip turns into duplicate database entries, corrupted state, and a cascading retry storm that takes down the system.
Approach: This session moves past architectural theory and dives into the practical reality of building truly idempotent APIs and asynchronous workers. Will look at how to safely manage state and handle duplicate events using Google Cloud Pub/Sub, Cloud Run.
Proof: I'll walk through a realistic, high-throughput system scenario, demonstrating exactly how to implement idempotency keys, manage atomic transactions, and configure Dead Letter Queues (DLQs) to catch unprocessable messages before they poison the queue.
Outcome: By designing for failure, we shift from hoping the network is reliable to building systems that absorb retries gracefully. This ensures absolute data integrity and system stability, even when traffic spikes or downstream dependencies degrade.
Takeaways: You will leave with actionable strategies for implementing idempotency in your code, configuring Pub/Sub retries without overwhelming your database, and using circuit breakers to protect vulnerable microservices.
Whats next: We will briefly look at how modern developer frameworks are evolving to handle these distributed state problems natively, reducing boilerplate and letting us focus on business logic.
Beyond Prompt Engineering: Building Reliable AI Agents with Context, Memory & Guardrails
Large Language Models have made AI applications easier to build than ever before—but creating an AI application that is reliable, scalable, and production-ready is a completely different challenge.
As developers move beyond simple chatbots and into agentic systems, prompt engineering alone is no longer enough. The real engineering challenge lies in designing systems that effectively manage context, memory, tool execution, and safety while maintaining predictable behaviour in production.
In this session, we'll explore how modern AI agents are built using context engineering, memory architectures, Model Context Protocol (MCP), retrieval strategies, tool calling, and guardrails. Through practical examples and real-world architectural patterns, we'll discuss why many AI applications fail in production and the engineering principles that make them dependable.
Whether you're experimenting with AI features or planning to integrate intelligent capabilities into your applications, you'll leave with a practical framework for building AI systems that are not only powerful—but trustworthy and production-ready.
Beyond the Chatbot: Hardening Asynchronous Agentic Workflows on Cloud Run & Eventarc
The Problem: Moving AI agents from Python notebooks to mission-critical backend systems reveals a harsh reality: traditional request-response micro-services break under agentic workloads. Multi-step LLM reasoning loops introduce long-tail latency, non-deterministic timeouts, and cascading failures across downstream APIs.
The Approach: To solve this, we must decouple synchronous user endpoints from multi-turn agent execution loops. This talk walks through building an event-driven choreography architecture using Google Cloud Run, Eventarc, and Firestore to manage asynchronous agent workloads at scale.
The Proof: I will demonstrate a concrete architectural blueprint where state machines and checkpointing are used to resume agent workflows after mid-execution timeouts or tool-call failures without re-running expensive context tokens.
The Outcome: By adopting event-driven patterns, systems achieve resilient rate-governance, implement circuit-breaking when downstream models degrade, and eliminate synchronous blocking in core services.
The Takeaways: Attendees will learn how to enforce concurrency limits on Cloud Run for LLMs, handle state persistence during agent loops, and implement distributed tracing across agent thoughts, tool invocations, and database mutations.
What is Next: As standards like Google's A2A protocol mature, asynchronous event-driven foundations will become the mandatory baseline for secure, multi-agent interoperability in the cloud.
Architecting Beyond Retries: Designing Resilient, High-Throughput Distributed Backends
In high-throughput microservices and distributed transaction environments, basic retry loops and naive backoff strategies frequently turn temporary network hiccups into cascading outages and thundering herds. Ensuring high availability and sub-50ms tail latencies requires proactive failure containment, deterministic state handling, and intelligent traffic shedding.
In this architecture-focused session, we deconstruct battle-tested engineering patterns for building fault-tolerant backend systems:
Blast-Radius Containment: Implementing bulkhead patterns and adaptive circuit breakers that isolate partial degradation without knocking out upstream services.
True Idempotency at Scale: Enforcing end-to-end consistency across async message brokers and distributed data stores using transactional outbox patterns, Redis locks, and deduplication tokens.
Taming Distributed State: Practical strategies for decoupling monolithic transactions into event-driven Sagas, automated dead-letter queue (DLQ) triage, and zero-data-loss reconciliations.
Database & Socket Preservation: Mitigating connection starvation and socket exhaustion through connection pooling optimizations, backpressure orchestration, and read/write splitting.
APIs in the Agentic Era- Building Low-Latency, Safe Backend Interfaces for MCP
Large Language Models and autonomous agent systems are only as capable as the backend APIs backing them. However, exposing enterprise backend systems to non-deterministic agent callers breaks traditional assumptions around rate limiting, connection pooling, and payload validation.
This talk breaks down how backend engineers can build and scale production-grade MCP (Model Context Protocol) servers and agent-facing interfaces on top of existing services:
From REST/gRPC to Tool Interfaces: Structuring self-describing schemas, dynamic parameter sanitization, and strict input boundaries to eliminate prompt injection via payload parameters.
Taming Non-Deterministic Traffic: How agentic retry loops and multi-step reasoning chains alter backend traffic profiles—and why standard API rate limiters fail against agent workloads.
Stateful Sessions over Stateless Backends: Managing persistent context, Server-Sent Events (SSE), and connection lifecycle without draining socket pools.
Telemetry & Cost Tracking: Tracing request lineages across LLM tool invocations down to backend database queries to catch latency regressions and token bleed.
3 Key Takeaways for Attendees:
Step-by-step guidance on designing lightweight, backward-compatible MCP layers atop enterprise REST and microservice architectures.
Defensive security patterns: sandboxing tool execution, scoped authorization tokens, and payload validation.
Observability patterns for profiling p99 latency regressions when tools are executed inside complex agent reasoning loops.
Anatomy of a Production Outage: Hard-Learned Lessons in Resiliency
In high-scale distributed systems, failures are not a possibility—they are a certainty. Whether it’s an unexpected traffic surge, cascading micro-service timeouts, or downstream database contention, resilience must be architected from day one.
Drawing from hands-on production experience building and scaling high-throughput backend services across fintech and travel-tech, this talk deconstructs real-world outages and how to engineer deterministic recovery. We will examine practical architectural blueprints for fault isolation, graceful degradation, and self-healing systems natively on GCP.
Key Takeaways for Attendees:
Root-Cause Deconstruction: How cascading failure loops and thundering herds propagate across microservices—and how to stop them at the network boundary.
Observability in Action: Leveraging Google Cloud Operations Suite (formerly Stackdriver)—using Cloud Trace, distributed telemetry, and structured Cloud Logging to identify tail-latency degradation before users notice.
Resilience & Backpressure Patterns: Implementing distributed circuit breakers, exponential backoff with jitter, and dead-letter queue (DLQ) triage using Cloud Pub/Sub, Eventarc, and Cloud Run / Cloud Functions.
Automated Self-Healing & Traffic Management: Utilizing Google Cloud Load Balancing (GCLB) and serverless traffic splitting/canaries to shed load, trigger automated rollbacks, and maintain sub-second response times during partial zone or dependency degradation.
From Green Builds to 3 A.M. Rollbacks: Lessons from Thousands of Production Deployments
This session shares practical lessons from operating and deploying large-scale distributed systems using open-source technologies. Attendees will learn proven approaches for reducing deployment risk through progressive delivery, feature flags, observability, and rollback strategies. The talk focuses on real-world engineering challenges and actionable practices that teams can adopt immediately to improve reliability, resilience, and developer productivity across cloud-native environments.
Guardrails over Gimmicks: Scaling Developer Experience (DevEx) with Enterprise AI Toolchains
Just buying Copilot licenses for everyone doesn't make an engineering team faster but often just creates more code debt to review. This session covers how to build a mature AI engineering culture by integrating AI toolchains directly into internal developer platforms (IDPs).
Key Takeaways:
How to measure actual engineering throughput and code quality improvements without creating toxic productivity metrics.
Setting up agentic workflows that help onboard engineers to complex, distributed cloud architectures faster.
Designing the "Human-in-the-Loop" review process so senior engineers spend time validating system design rather than fixing syntax.
Beyond the Prompt: Building Secure Quality Gates for AI-Driven Legacy Migration
Everyone talks about using AI to write new code, but the real enterprise headache is existing infrastructure. This talk explores how senior backend engineers can design strict testing and architectural "guardrails" (Quality Gates) around AI agents to modernize legacy systems safely.
Key Takeaways:
How to structure "Prompt-to-PR" workflows that automatically run comprehensive integration tests before a human even reviews the code.
Strategies for using AI to analyze, document, and break down monolithic backend services into microservices.
Real-world lessons on catching hallucinated dependencies or insecure code before it hits the main branch.
The Hidden Cost of AI on Kubernetes (And How to Fix It Before Finance Calls You)
Everyone is deploying AI.
Almost no one is measuring what it truly costs.
AI workloads behave fundamentally differently from traditional microservices — they are GPU-hungry, memory-intensive, bursty, and often poorly autoscaled. On Kubernetes, that translates into idle GPUs, oversized nodes, inefficient bin-packing, runaway inference scaling, and hidden infrastructure waste.
And the scary part?
Most teams don’t even see it.
In this deep-dive session, we’ll explore what actually happens when AI workloads hit production Kubernetes clusters — especially in cloud environments like Azure.
We’ll break down:
• Why traditional autoscaling strategies fail for inference workloads
• GPU scheduling, bin-packing, and resource fragmentation problems
• Cost traps in model serving architectures
• Observability patterns to detect waste before it becomes a budget crisis
• Designing cost-aware AI platforms on Kubernetes
• Practical architecture patterns that balance performance, scalability, and cost
This session is not about hype. It’s about infrastructure reality.
If you are a cloud engineer, architect, or platform builder deploying AI systems — this talk will give you the mental models and architectural patterns to run AI workloads responsibly at scale.
Because scaling AI without cost visibility is not innovation.
It’s liability.
Responsible AI: Building the Right Intelligence, Rightly
As AI rapidly integrates into every layer of technology, the real challenge is no longer what AI can do, but how responsibly it does it.
This session explores the core principles of Responsible AI; fairness, transparency, accountability, and safety and how developers can operationalize them through real-world practices like AI governance, bias detection, risk assessment, and ethical system design.
From understanding generative AI’s dual nature to embedding ethics into every model lifecycle, this talk will help participants learn how to build AI that’s not just intelligent, but also trustworthy, compliant, and human-centric.
Engineering at Scale: Lessons from Building High-Throughput Systems on Open Source Stack
Modern applications demand real-time processing, massive scalability, and zero-downtime reliability. But building systems that can handle millions of events without breaking is harder than it looks.
In this talk, I’ll share real-world engineering lessons from building and operating a cloud-native, event-driven platform using Java, Spring Boot, Apache Kafka, Docker, and Kubernetes.
We’ll walk through how to design scalable microservices architectures, build reliable event pipelines, run production workloads on Kubernetes, and handle failures, traffic spikes, and performance bottlenecks. I’ll also cover observability, autoscaling, and cost optimization using open-source tooling.
This session is focused on practical design decisions, proven architectural patterns, and production learnings that engineers can directly apply to build resilient, high-performance distributed systems.
Invisible AI: the AI of modern living, a silent revolution
Note: SLIDES ARE RAW, and are subject to more improvement and additions, please do not consider it final, happy to be reached out for more info.
This talk uncovers how Artificial Intelligence is already embedded in our daily lives, often in ways we don’t even realize. From fraud detection in banking to Netflix recommendations, Uber surge pricing, spam filters, and real-time traffic predictions, AI is silently powering the systems we rely on every day. The session makes these invisible integrations relatable and easy to understand through real-world examples and interactive discussions.
Key Takeaways
• Understand how AI powers everyday experiences we often take for granted.
• Discover real-world applications of AI in finance, entertainment, e-commerce, and travel.
• Learn how Cloud technologies enable these AI-driven services at scale.
• Gain a new perspective on how AI shapes convenience, security, and decision-making behind the scenes.
• Leave with curiosity to spot invisible AI in your own daily routines.
Who Should Attend
• Tech professionals curious about practical AI applications.
• Students and early-career engineers who want to connect theory with real-world impact.
• Non-technical participants looking to understand AI’s everyday role without heavy jargon.
• Community members and enthusiasts who want to explore how AI quietly influences modern living.
Code That Thinks: Designing AI-Native Software Systems for the Next Decade
Artificial intelligence is no longer just a feature bolted onto existing products-it is rapidly becoming the foundation upon which modern software is built. This shift demands a fundamental rethink of how we design, develop, deploy, and scale applications.
In this session, we'll explore what it truly means to build Al-native systems: applications where intelligence is woven into the architecture itself, not merely layered on top. From orchestrating LLM-powered workflows and designing resilient human-in-the-loop systems to managing observability, cost, governance, and trust, we'll examine the architectural patterns that define the next generation of software.
Through real-world examples, practical design principles, and a live demonstration, attendees will learn how to move beyond experimental Al integrations and engineer production-ready intelligent systems that are scalable, reliable, and responsible.
Whether you're building internal developer tools, customer-facing products, or enterprise platforms, this session will equip you with the frameworks needed to create software that doesn't just execute instructions-but reasons, adapts, and evolves.
From Chaos to Control: AI-Optimized Kubernetes Workflow Management
As cloud-native systems scale, managing Kubernetes clusters has become increasingly complex. This session introduces how AI-driven tools are transforming Kubernetes workflows, from automating CI/CD pipelines to optimizing resource allocation and anomaly detection in production. We will explore cutting-edge open-source AI projects that integrate seamlessly with Kubernetes, demonstrating real-world applications that reduce human intervention while improving efficiency and reliability.
Attendees will leave with actionable insights and practical knowledge to adopt AI-powered automation in their Kubernetes environments effectively.
Innovating with Hybrid Agile: Merging Scrum and Kanban to Build Smarter Products
Building innovative products requires more than just sticking to standard Agile frameworks. Hybrid Agile blends the discipline of Scrum with the adaptability of Kanban, empowering product and tech teams to innovate faster and smarter.
This session will delve into
How combining Scrum and Kanban fosters a culture of continuous innovation.
Practical workflows and tools to align product vision with engineering delivery.
Real-world examples of successful product launches using Hybrid Agile.
Strategies for overcoming bottlenecks in product discovery and development cycles.
Attendees will learn how to adapt this approach for faster MVPs, seamless stakeholder collaboration, and a clear innovation roadmap.
Ethical decision making with Responsible AI
Introduction to responsible AI: Responsibility in the context of AI refers to ensuring that artificial intelligence systems are designed, developed, and deployed in an ethical, transparent, and accountable manner. This includes mitigating risks, protecting privacy, ensuring fairness, and making sure that AI does not harm individuals or society. Responsibility is not just about the behavior of the AI itself but also about how it is used by the people who create, regulate, and interact with it.
- Also, how different organisations define it in their ways.
In the context of AI, "Parampara" can be understood as the tradition of responsible creation and ethical use of technology. “Pratishtha" can be understood as the foundational establishment of AI systems that are built upon clear ethical guidelines and societal values. "Anushasan" refers to the discipline or regulation needed when developing and using AI systems.
Responsibilities of AI (Building AI Right). Components of the right AI
Responsibilities towards AI as developers, creators, users.
DOs and DON’Ts
Interesting references and a case study for accenture: https://www.accenture.com/us-en/case-studies/data-ai/blueprint-responsible-ai
Reaching Cloud 9 with Google Cloud’s GenAI tools
Cloud Nine isn’t just a phrase: it’s how developers feel with the new Gen AI tools from Google Cloud. Exploring how Google Cloud’s cutting-edge Gen AI tools are revolutionizing development, business operations, and end-user experiences; all while staying efficient, scalable, and accessible to everyone.
Includes the introduction to capabilities of tools like gemini, vertex AI, autoML and many more.
Devfest Mumbai 2025 Sessionize Event
Snigdha Kashyap
Contributing to #Tech as SDE-2 @ExpediaGroup
Gurugram, India
Actions
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top