
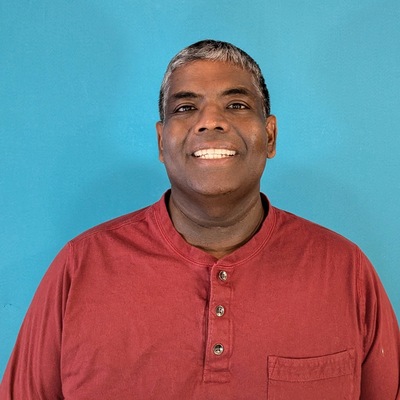
Sujee Maniyam
Developer Advocate @ Nebius
San Jose, California, United States
Actions
Sujee Maniyam is a Developer Advocate at Nebius, with a background spanning AI, distributed systems, data engineering, and cloud infrastructure. Outside of work, he is usually on a local pickleball court. You can find more of his work at [sujee.dev](https://sujee.dev/)
Links
Tracing an LLM Request: From API to GPU and Back
## Abstract
You call an LLM API. A few seconds later, tokens start streaming back. But what actually happens in between?
In this **visually driven talk**, we'll follow a single request from the client to the GPU and back. Through animated visualizations, we'll explore how the different systems work together, where latency comes from, and the optimizations that make inference faster.
## Description
When you call an LLM API, a complex system springs into action. Your request passes through gateways, tokenizers, routers, and schedulers before reaching the GPUs that run the model. Along the way, infrastructure decisions and optimizations determine how quickly the first token arrives and how fast the rest of the response is generated.
But how does all of this actually work?
Rather than explaining LLM inference as a collection of disconnected concepts, this session takes a different approach: **we'll follow a single request, step by step, from API call to GPU execution and back to the client.**
Through animated visualizations and practical examples, we'll explore:
- How the different components of an LLM inference pipeline work together
- How production systems optimize inference performance
- How to understand key performance metrics such as time to first token (TTFT), decode speed, and end-to-end latency
At each stage, we'll answer three practical questions: What happens here? What slows it down? And which optimizations help, at what cost?
By the end, you'll understand how production LLM serving systems fit together, where performance bottlenecks arise, and how to reason about improving inference performance.
## Key Takeaways
You'll leave with a practical mental model of LLM inference, an understanding of common performance bottlenecks, and insight into how production inference systems optimize performance. No machine-learning background required.
https://sujee.dev/talks/tracing-an-llm-api-request/
## Audience
Software engineers, backend developers, platform engineers, and AI application developers who want to understand what happens behind an LLM API.
## Talk Level
Intermediate
## Duration
45 mins
Coding with open models
## Abstract
This demo-driven talk will show how to use open models with popular coding agents like OpenCode, Hermes, Claude and Cursor
## Description
Coding agents such as OpenCode and Claude Code are fundamentally changing software development workflows. Most teams, however, still rely primarily on proprietary frontier models.
In this demo-driven session, I will show how to pair modern coding agents with high-performance open models running on Nebius Token Factory, with a focus on developer experience, model behavior, considerations relevant to production use.
Attendees will receive platform credits for getting started immediately with open-model-powered coding agents.
## Key Takeaways
- Learn to connect open models with coding agents
- Leave with credits to the platform to start experimenting with the models
Optimizing Open Models for Production Grade Inference
Open-source foundation models are rapidly closing the gap with proprietary systems, enabling organizations to build powerful AI applications with greater flexibility and control. However, deploying these models in production introduces a new set of challenges: latency, throughput, scalability, and cost efficiency.
In this talk, we’ll explore the modern inference optimization techniques that power large-scale AI systems in production. Topics include KV cache optimization, cache-aware routing, prefill/decode disaggregation, speculative decoding, and other emerging approaches used to improve performance and reduce infrastructure costs.
Through practical examples and real-world architecture patterns, attendees will gain a deeper understanding of how to run open models efficiently at scale.
State of Open Models in 2026
## Abstract
Leading open models now compete with closed frontier models on many coding, reasoning, and agentic tasks. This talk maps the late-2026 landscape, compares model capabilities and production costs, and explains how to choose the right model for each workload.
## Description
Choosing an open model is no longer a simple trade of capability for control. Leading open models now compete with closed frontier models on important workloads, but the right choice still depends on the task, latency targets, deployment model, and budget.
In this session, we will compare current models from the Qwen, DeepSeek, Kimi, GLM, MiniMax, and Llama families. We will address three practical questions:
- **How good are they really?** A review of benchmark results, including where open models lead and where gaps remain.
- **What do they cost in production?** A comparison of pricing and cost per task for open and proprietary models.
- **Which model fits each job?** Practical guidance for choosing a model based on your workload, performance goals, and budget.
You will leave with a practical map of the open-model ecosystem and a framework for comparing capabilities, costs, and workload fit.
## Key Takeaways
- A clear view of open and closed model capabilities in late 2026, including strengths, gaps, and best-fit use cases
- A practical method for comparing pricing and cost per task across models
- A framework for selecting models based on workload, performance goals, and budget
## Talk Level
Beginner to intermediate
## Audience
AI engineers and technical leaders evaluating open models for production.
## Duration
45 to 60 minutes
## Session Type
Talk
LLM Inference Benchmarks: Demystified and Explained
## Abstract
TTFT, TPOT, ITL, end-to-end latency, tokens per second: inference benchmarks are full of acronyms.
In this demo-driven talk, we’ll follow one streamed request from dispatch to final token. Along the way, we’ll show what each common metric measures and how it maps to user experience. Then we’ll tour popular benchmarking tools and run one live. You’ll leave knowing how to design a fair benchmark, interpret the results, and choose the metrics that match your application.
## Description
A benchmark number means little unless you know what was measured, on which workload, and under how much load. Two endpoints can both claim to be fast and still behave very differently for real users.
We start by tracing a single streamed request from the client to the GPU and back to see where the time goes. Along the way, we explain time to first token (TTFT), time per output token (TPOT), inter-token latency (ITL), end-to-end latency, and throughput.
Through side-by-side examples, we show how these metrics trade off. One endpoint might start fast but stream slowly. Another might be quick for a single user but degrade under concurrency. A third might post high aggregate throughput while each individual user waits. We also show why averages hide tail latency, and why p95 and p99 often matter more than the mean. Finally, we look at how prompt length, output length, concurrency, cache state, generation settings, errors, and the network path can each shift the numbers.
With those foundations in place, we compare three tools built for different needs:
- **vLLM Benchmark CLI** measures serving performance with configurable workloads and concurrency.
- **NVIDIA GenAI-Perf** generates load and reports latency and throughput for generative AI endpoints.
- **ZebraBench** runs in the browser and compares OpenAI-compatible endpoints with no local Python setup.
We’ll then do a couple of benchmarks, compare the results across repeated runs
## Key Takeaways
- Understand TTFT, TPOT, ITL, end-to-end latency, and throughput, and how each maps to user experience
- Distinguish single-request speed from system capacity, and use percentiles to expose tail latency
- Design fair benchmarks by controlling workload, settings, cache state, and concurrency
- Choose the right tool, from quick browser-based comparisons to controlled load tes
## Talk Level
Beginner to intermediate
## Audience
AI engineers and platform engineers who select, operate, or compare LLMs and inference endpoints
No prior experience with inference benchmarking is required.
## Duration
45 minutes
Harness Engineering 101: What Makes an AI Agent Finish the Job?
## Abstract
How does an AI agent know what it can do, what happened after it tried, and when the job is done? This talk introduces harness engineering, the practice of designing the software around a model that gives it context, runs its tools, and checks its work. You’ll learn how those pieces fit together and see them in action in a short coding-agent demo.
## Description
When you ask a coding agent to fix a bug, the model can propose an action like reading a file or running a command. The harness checks whether that action is allowed, executes it, and sends the result back to the model. The model uses that result to choose its next action. That cycle is the agent loop.
Harness engineering is about designing what happens around that loop. We’ll explore four decisions every agent builder faces.
- **Context.** What does the model need to see to make its next decision? That might include repository instructions, relevant files, and the results of earlier actions.
- **Tools and permissions.** What can the agent do, and which actions require a person’s approval?
- **Feedback and recovery.** When a command fails, what information helps the agent choose a better next step? When should it retry or ask for help?
- **Verification and stopping.** What evidence shows the task is complete? When should the harness end a run that’s going in circles?
A short Python demo will make those decisions concrete. We’ll give the same model the same bug twice and change one thing about the harness. In the second run, it can run tests and use failures to guide its next attempt. We’ll follow the tool calls and results to see how the feedback changes what the agent can do next.
## Key Takeaways
- Explain what an agent harness does and how it works with the model and its tools.
- Identify the design decisions behind context, permissions, feedback, and stopping conditions.
- Use an execution trace to see what the agent knew, what it tried, and where it got stuck.
- Define what counts as a completed task and how the harness can verify it.
## Session Type
Talk with a short live demonstration
## Talk Level
Beginner
## Audience
Software developers and engineers who want to understand how AI agents work or are considering building one. Basic Python familiarity helps with the demo. No prior experience with LLM APIs or agent frameworks is required.
## Duration
45 minutes, including 5 minutes for Q&A
Sujee Maniyam
Developer Advocate @ Nebius
San Jose, California, United States
Links
Actions
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top