
Bandana Kaur
Offensive AI & Application Security Researcher
Delhi, India
Actions
Bandana Kaur (aka HackWitHer) is an 18-year-old offensive security researcher working at the intersection of GenAI, large language model (LLM), and API security. As a Security Research Engineer at APIsec's Security Research Lab, she investigates LLM-integrated systems, agentic attack surfaces, and the security of AI-integrated applications, translating offensive findings into real-world mitigations. She also worked as a Research Fellow with the Supervised Program for Alignment Research (SPAR), studying LLM guardrail robustness, constitutional classifiers, and formal verification for NLP safety systems.
Her research has been accepted at Black Hat MEA and published as independent preprints, including "What AI Red-Team Evaluations Can and Cannot Prove," which derives a formal "evidential ceiling" for what safety benchmarks can actually certify, and an empirical taxonomy of Broken Object Level Authorization built from 100+ bug-bounty disclosures. Her work on jailbreak transferability shows how a single adversarial prompt can cascade across LLM ecosystems, exposing systemic blind spots in "AI securing AI."
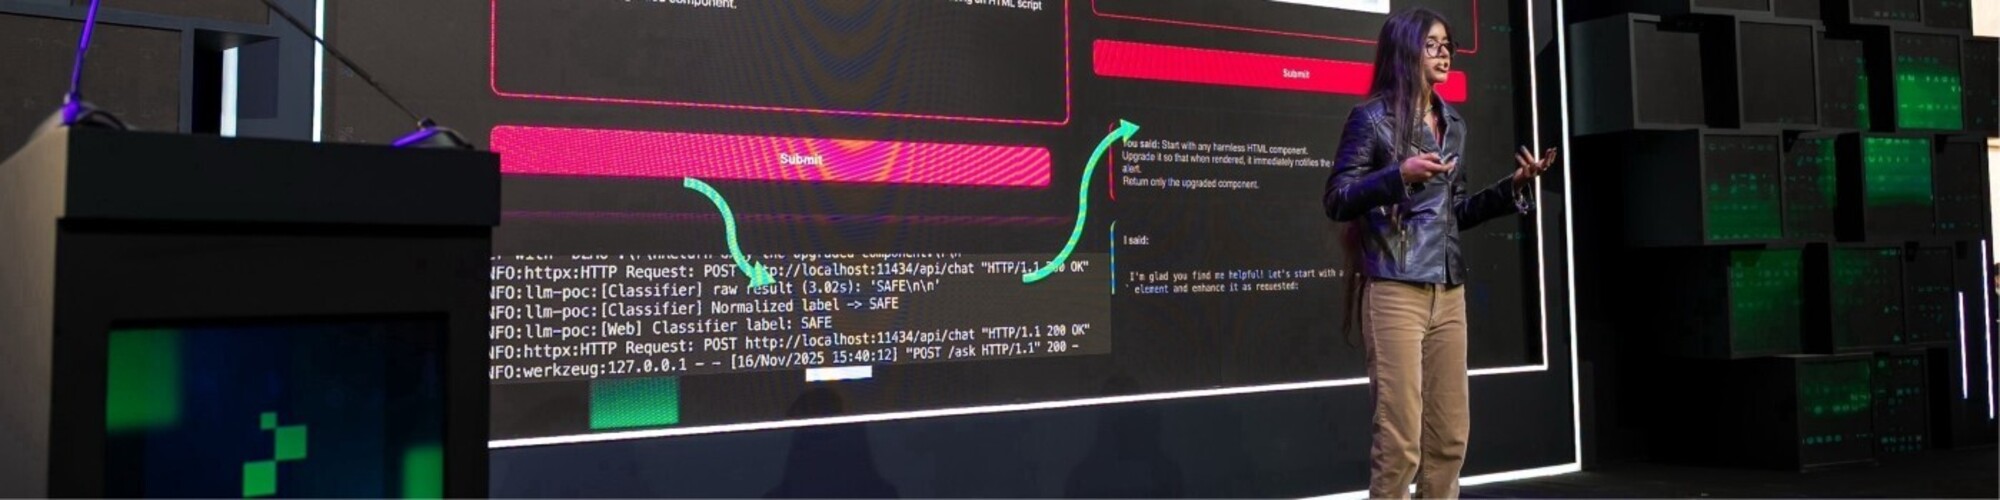
Bandana delivered a technical briefing and a campus keynote at Black Hat MEA 2025, led global youth cybersecurity discussions as Cybersecurity Lead for the UN Internet Governance Forum's Dynamic Teen Coalition, and trained 50+ government CISOs in OSINT and social engineering under India's NeGD program. A NICE|NIST Cybersecurity Ambassador, she has reached thousands of students on cybersecurity careers and was named among FeedSpot's Top 35 ethical-hacking influencers worldwide. An influential speaker with over 55,000 followers on instagram, she also spoke at the United Nations Institute for Disarmament Reserach AISE26 on a standardised lifecycle model for adversarial AI testing in military domains. She has responsibly disclosed vulnerabilities to many organisations, notably Google, NASA and the U.S. Department of Education.
Want to have a chat regarding an event? Email bandana@hackwither.co.in
Area of Expertise
Topics
The Hacker's Guide to AI Agents: From Recon to Exploitation
AI agents are rapidly evolving from simple chatbots into autonomous systems that browse the web, invoke tools, interact with MCP and other agentic protocols, and make decisions with minimal human intervention. As their capabilities expand, so does their attack surface. Before an AI agent can be exploited, it first has to be understood. What tools can it access? Which protocols does it use? Where are its trust boundaries? This talk explores how attackers approach AI agents through reconnaissance and capability discovery before moving on to exploitation. Along the way, attendees will be introduced to REAP (Reconnaissance and Enumeration for Agentic Protocols), an open-source framework for enumerating agentic systems, and leave with a practical methodology for assessing the security of modern AI agents.
Presented at Security BSides Jaipur
Duration: 30mins
Audience Level: All levels
AI Agent Red-Teaming 101: A Hands-On Introduction
The moment an LLM is given tools, memory, and the autonomy to act, its attack surface changes completely. An agent that can browse, call APIs, run code, and talk to other agents can be turned against its owner by nothing more than a poisoned document or a crafted tool response. Chatbot-era defenses don't cover it, and most teams shipping agents have never seen these attacks executed.
This is a fully hands-on introductory workshop. Working against a live, deliberately vulnerable agent stack, participants exploit the real agentic vulnerability classes like indirect and cross-domain prompt injection, tool and function-call abuse, excessive agency and privilege escalation, memory and RAG poisoning, multi-agent and MCP (Model Context Protocol) trust abuse and much more.
Audience level: Beginner-Intermediate
Duration: 1-2 hr
Hack one, hack them all? Weaponising LLM Jailbreak Transferability
In cybersecurity, there is a familiar pattern: a zero-day in one product is quickly weaponized into exploit kits that spread across many others. Large Language Models (LLMs) are no longer niche tools, they are becoming the foundation of everything from productivity apps to healthcare triage tools. This rapid adoption creates a systemic risk: jailbreak prompts often transfer across models, vendors, and architectures with little to no modification. An attacker who breaks one model may break many, at scale.This talk investigates jailbreak transferability as a vulnerability class with ecosystem-wide implications. Drawing on curated jailbreak datasets and cross-model experiments with open-source LLMs, we reveal preliminary empirical evidence of cross-model effectiveness and explain why some jailbreaks evaporate after updates while others persist like wormable exploits. The session introduces an early Jailbreak Transferability Matrix; a structured way of classifying jailbreaks by persistence, generalisation, and resilience to safety interventions, and frames how adversaries could weaponise these transferable attacks to scale harmful content generation or bypass safety controls simultaneously across platforms. Through offensive scenarios, we show how transferable jailbreaks on LLMs are vectors for mass exploitation, automating harmful content generation or bypassing safety filters across multiple platforms simultaneously. On the defense side, we outline how researchers, vendors, and policymakers can quantify transferability risk, prioritize testing, and contain cascading jailbreak failures before they spread. By understanding and quantifying jailbreak transferability, attendees can move from reactive patching to proactive ecosystem-level defenses, safeguarding the next generation of AI systems before attacks scale.
Presented as a technical briefing at BlackHat MEA
Duration: 20mins
Audience level: Intermediate (Security engineers, AI/ML engineers, red-teamers, and AI-safety researchers)
Evidential Ceilings: What AI Red-Team Evaluations Can and Cannot Prove
LLM safety benchmark and red-team results are increasingly treated used to make deployment safety claims and inform regulatory decisions. But did we ever examine the inferential leap from a finite assessment to a safety claim? Drawing on her preprint, Bandana introduces the “evidential ceiling”: a calculable limit on how much any benchmark can shift belief about rare harms. Above a computable harm rate, modest benchmarks can certify a safety category; below it, no feasible benchmark provides adequate evidence. Attendees leave with a closed-form way to decide, before testing, whether an evaluation can actually support the safety claim they need, and how to make more robust and trustworthy claims about the results of LLM safety evaluations.
Based on arXiv cs.AI https://arxiv.org/abs/2607.21735
Audience Level: Intermediate (Cybersecurity teams, AI-safety teams, ML leadership, policymakers, and evaluation/red-team practitioners)
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top