
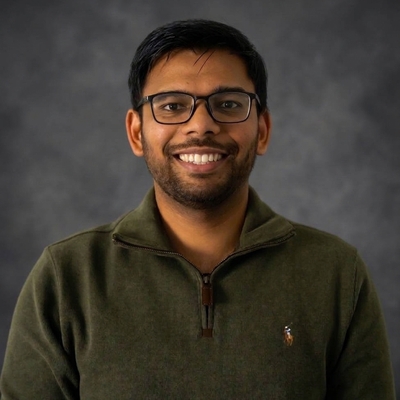
Harshul Jain
Audible, Senior Software Engineer
Newark, New Jersey, United States
Actions
I'm Harshul Jain, a Senior Software Engineer at Audible, where I build ML and LLM infrastructure for production-scale systems. My work spans real-time fraud detection, content intelligence, GenAI semantic search serving 10M+ customers, and a real-time ML feature store processing 100K TPS across 20+ use cases. I'm the author of LLM Inference at Scale, an open-source, benchmark-driven handbook on GPU memory engineering, KV cache optimization, attention, quantization, speculative decoding, and production LLM serving. The project received 160+ GitHub stars in its first month. I've delivered a 2-hour LLM inference workshop at the AIE World Fair, I'm speaking at ODSC 2026, and I give guest lectures at NYU. I also created AgentShip, an open-source framework for deploying AI agents to production.
Area of Expertise
Topics
Saying No: Admission Control When Your Coding Agent Overwhelms Your Own LLM
## Background
When a coding agent fans out into forty parallel tool calls against an LLM you host yourself, the interesting failure is not the model or the engine. It is the seam between them. This talk is about the layer that decides which requests to accept before they touch the GPU, and what a systematic review of fifty five papers says most people are getting wrong about it.
## Abstract
Coding agents do not send one request at a time. They fan out, they retry, and they burst. If the LLM they hit is one you host yourself, the natural failure mode is not that the model is wrong or the engine is slow. It is that your inference layer accepts every request and then buries the ones you actually needed to finish first.
Admission control is the seam that decides which of those requests to accept and which to refuse before they touch the GPU. The theory is old, the practice on LLM serving is barely started, and the sixteen published policies compare against different engines, different traces, and different baselines, so nothing lines up. A systematic review of fifty five papers across OSDI, SOSP, NSDI, MLSys, ASPLOS and EuroSys finds one uncomfortable fact underneath the mess: none of the sixteen policies report the operating range of the signal they read on. A policy that watches KV pressure will happily admit every request while the signal never leaves a narrow band, and its results table will look ordinary.
This talk walks through the five questions to ask about any admission policy before you deploy it under a coding-agent load (unit, setting, objective, signal, portability), maps eight real production incidents at OpenAI, Anthropic, Cloudflare and Azure onto the admission failure modes the literature already names, and shows the probe that catches a policy whose signal never moves. You leave with a checklist you can use on Monday and a clear picture of why the layer under your coding agent is the one your postmortems keep naming.
## Takeaways
- Why admission control is the layer under your coding agent that decides whether your GPU stays useful, not just busy.
- A five-question checklist (unit, setting, objective, signal, portability) for evaluating any published admission policy before it goes near your stack.
- Why the sixteen published policies do not compare cleanly, and the one reporting item that would fix it if authors added it.
- How eight real production incidents at OpenAI, Anthropic, Cloudflare and Azure map onto admission failure modes the literature already names.
- A probe you can run against your own inference stack in an afternoon to catch a policy whose signal never actually moves.
Extra Resource:
- AdmitPerf - github.com/harshuljain13/AdmitPerf
- LLM Inference at scale - https://github.com/harshuljain13/llm-inference-at-scale/tree/master
Securing the Agentic Tool Layer: A Runtime Defense Framework for MCP Agent Deployments
Most LLM safety work guards the user prompt. MCP agents face a different problem: the attack arrives through the tools the agent already trusts. A poisoned tool description, a hidden instruction in a tool response, or a malicious server pulled from a public registry can hijack an agent without ever touching the user.
This session walks through a threat taxonomy built from 80+ techniques catalogued under SAFE-MCP, a Linux Foundation/OpenSSF project, then shows a runtime proxy that validates tool calls and responses inline, with no changes to the agent or server. In red-team testing across five model backends, it cut tool-poisoning success from 74% to under 9% and indirect injection from 47% to under 6%, adding under 120ms per call.
Attendees leave with a concrete defense architecture, the false-positive tradeoffs that matter in production, and what to vet before approving an MCP server for their stack.
2 hr deep dive on LLM Inference at Scale
Most engineers using LLMs can call an API. Far fewer can explain why their model is slow, why it's running out of memory, or how the inference engines powering every major LLM API actually work.
This workshop walks through the full inference stack — from how a transformer generates a single token to serving billions of tokens a day with vLLM, SGLang, TensorRT-LLM, Ray, and KServe/llm-d. 60% explanation with live demos, 40% hands-on exercises. Attendees leave with a running vLLM server they benchmarked themselves.
Based on the open-source practitioners handbook being built live at github.com/harshuljain13/llm-inference-at-scale
Beyond Frameworks: Building Runtime-Agnostic AI Agents
AI agent frameworks are proliferating - Google ADK, LangGraph, OpenAI Agents SDK, CrewAI - each with distinct paradigms, tool interfaces, and deployment models. Meanwhile, tool integration standards like MCP (Model Context Protocol), memory solutions like mem0 and Supermemory, and observability platforms like LangFuse and Opik are emerging to solve interoperability, but adoption remains fragmented. Teams invest months building agents on one framework with tightly coupled memory, observability, and tooling systems, only to discover they need capabilities from another. The result? Rewrites, lock-in, and production delays.
This talk introduces a different approach: runtime-agnostic agent architecture. Instead of coupling agent logic to a specific framework, we separate what the agent does from how it executes. Write your agent once, run it on any engine and integrate tools and memory through standardized abstractions.
Drawing from AgentShip an open-source production layer for AI agents, we'll explore:
- **The Pluggable Engine Pattern**: An `AgentEngine` abstraction that enables swapping ADK for LangGraph (or future runtimes) without touching agent code
- **MCP Integration Layer**: Standardized tool discovery and invocation using Model Context Protocol, making tools portable across frameworks
- **Pluggable Memory Systems**: Abstracted short-term and long-term memory with support for custom implementations, mem0, Supermemory, or simple in-memory stores
- **Pluggable Observability**: Framework-agnostic tracing and monitoring with support for LangFuse, Opik, or custom observability backends
- **Declarative Agent Configuration**: YAML-driven definitions that eliminate framework-specific boilerplate
- **Unified Streaming & Sessions**: Consistent behavior across engines with three streaming modes and pluggable session storage
- **Agent-to-Agent Orchestration**: Hierarchical multi-agent workflows where sub-agents become tools
We'll demonstrate these patterns through an health AI assistant where a primary agent orchestrates five specialized sub-agents for conversation analysis, medical reports, and action tracking all running on interchangeable backends.
Attendees will leave with architectural patterns they can apply immediately, whether building new agent systems or refactoring existing ones away from framework lock-in.
CNCF-Hosted Co-located Events North America 2026 Sessionize Event
AI Engineer World's Fair 2026 Sessionize Event
MCP Conference New York Sessionize Event
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top