
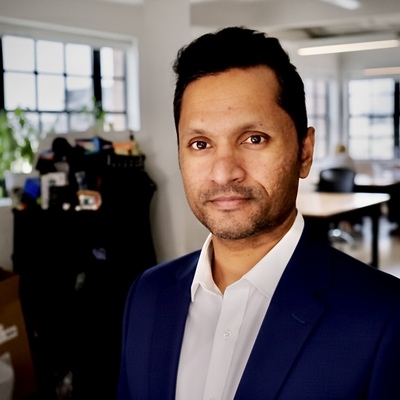
Sidharth Gopakumar
Speaker at IEEE InC4 2026 | Product Manager, AI | Molecule Software
Boston, Massachusetts, United States
Actions
Sidharth Gopakumar is a product manager at Molecule Software, where he leads product development for an energy trading platform used by hedge funds and Fortune 100 energy companies, processing nearly $100B in commodity value daily. Before that, he built conversational GenAI and vector search infrastructure at a YCombinator-backed enterprise startup, taking the platform from zero to 10 enterprise customers. He has published IEEE research on predictive AI frameworks and prescriptive analytics in operations.
Area of Expertise
Topics
The Signal Stack: How PMs Combine Tickets, Sentiment, and Usage Into One Risk Call
In consumer SaaS, churn often shows up in declining logins and engagement. In enterprise B2B platforms, it is quieter. Customers still sign in, file tickets, and attend QBRs, while the renewal decision is already forming months earlier.
This talk covers how product teams can combine heterogeneous signals into one account-risk call, drawing on firsthand work building an account-health and churn-risk system at Molecule, a cloud-native energy trading platform processing about $100 billion in commodity value daily.
The core argument: operational and relationship signals (support tickets, CST sentiment, complaints, usage gaps) often predict risk better than session counts alone. The hard problem is rarely a fancier model. It is stacking signals, weighting them with product judgment, and turning the output into a clear next action for account teams.
The session walks through a practical signal-stack framework and defensible outcomes from shipped work: identifying elevated risk about 6 to 8 weeks earlier than prior processes, and reducing account-manager labor by roughly $23K per year across about 100 accounts through better prioritization. Related reporting consolidation on the same platform saves customers about $100K to $150K per year in implementation and operational overhead where adopted.
What Commodity Trading Platforms Teach Product Teams About AI Under Uncertainty
Enterprise AI talks often assume clean labels, stable users, and a forgiving failure mode. Commodity trading platforms do not. Prices move continuously. Regulations differ by market. Integrations fail in partial, ugly ways. Operators need decisions under uncertainty, not another dashboard of predictions.
This session shares product lessons from building AI and data products inside a cloud-native energy trading and risk management (ETRM) environment that processes about $100 billion in commodity value daily. The focus is transferable: how product managers should design AI when wrong answers, delayed data, or brittle workflows have real operational cost.
We cover three themes. First, uncertainty is a first-class product requirement: confidence, fallbacks, and human override matter as much as model accuracy. Second, the best signals are often operational (exceptions, latency, reconciliation friction, support patterns), not vanity engagement metrics. Third, "prescriptive" beats "predictive": the system should recommend or trigger the next action, not only score risk.
Attendees leave with a practical lens for AI roadmaps in any high-stakes B2B domain: trading, finance, logistics, or regulated operations. Examples stay vendor-agnostic and emphasize product judgment over tooling hype.
RAG in Production: What Breaks After the Happy Path
A retrieval demo on a clean corpus looks easy. Production RAG breaks in quieter ways: wrong chunk boundaries, stale indexes, permission leaks across tenants, "confident" answers with weak grounding, and evaluations that never catch regressions.
This talk covers product and architecture lessons from shipping enterprise retrieval systems, including RAG, vector search, and LLM orchestration from pre-revenue through early enterprise customers, plus constraints learned working alongside high-stakes operational software. We focus on failure modes after the happy path: what to measure, what to gate before release, and how product managers should prioritize fixes when everything looks "fine" in a pilot.
Attendees get a production checklist: indexing and refresh, access control, evaluation harnesses, fallback behavior, and operator UX when the system should abstain. Examples stay vendor-agnostic. No FHIR. No tooling pitch.
RAG and Enterprise Search in Production: What Breaks After the Demo
Shipping search and RAG that operators trust in production is hard. This talk covers product and architecture lessons from building enterprise GenAI retrieval systems: tradeoffs, evaluation that catches silent failures, access control and tenancy, and governance so answers stay auditable. Examples draw from taking a conversational GenAI platform from pre-revenue to enterprise customers, and from working in regulated trading environments where wrong answers have real cost. Attendees leave with a short production checklist and failure modes to design against before the next pilot.
RAG in Production: What Breaks After the Happy Path
A retrieval demo on a clean corpus looks easy. Production RAG breaks in quieter ways: wrong chunk boundaries, stale indexes, permission leaks across tenants, confident answers with weak grounding, and evaluations that never catch regressions.
This talk covers product and architecture lessons from shipping enterprise retrieval systems (RAG, vector search, LLM orchestration) from pre-revenue to enterprise customers, plus high-stakes operational software lessons. It covers failure modes after the happy path: what to measure, what to gate before release, and how to prioritize fixes when a pilot looks fine.
Attendees get a checklist: indexing and refresh, access control, evaluation harnesses, fallback behavior, and operator UX when the system should abstain. Examples stay vendor-agnostic.
From AI Prototype to Enterprise Product: Building Governed, Trustworthy AI Systems
Enterprise AI projects often demonstrate impressive capabilities in a prototype but face very different challenges when they move into real-world environments. This session explores the product and governance considerations involved in taking AI systems from experimentation to enterprise adoption. Drawing on experience across enterprise B2B SaaS, AI/ML product strategy, data-driven products, and AI governance, the discussion will cover RAG, data quality, access and oversight, evaluation, human-in-the-loop controls, and measuring business value. The focus is on practical decisions teams can make to build AI systems that are useful, trustworthy, and scalable without allowing governance to become an afterthought.
Enterprise GenAI That Operators Trust: Governance Without Freezing Shipping
Governance is often framed as the enemy of speed: policies, reviews, and blocked releases. In enterprise GenAI, weak governance is what actually slows you down, through incidents, lost trust, and rework.
This talk covers how to ship GenAI with lightweight governance that operators and customers can trust. Drawing on building RAG and LLM systems for early enterprise customers, and on working in regulated trading contexts, it outlines a practical control set: data access and tenancy, evaluation before and after release, logging for audit, human escalation, and clear ownership when answers are wrong.
We discuss how product managers can keep a dual-track cadence: fast experiments in low-risk sandboxes, and higher bars for workflows that touch customers, money, or compliance. The goal is not zero risk. It is known risk, recoverable failure, and continuous learning without freezing the roadmap.
Attendees leave with a one-page governance checklist they can adapt to their stack.
Building AI Products for Operators, Not Demo Audiences
Many AI and agent products are optimized for a five-minute demo: fluent answers, a clean UI, one happy path. Operators running these in production need reliability under messy inputs, clear ownership of mistakes, and workflows that fit how work gets done.
Drawing on experience shipping GenAI infrastructure (RAG, vector search, orchestration) for enterprise customers and AI-assisted workflows in a high-stakes trading environment, this talk contrasts demo metrics (wow factor, clean-query latency) with operator metrics (task completion, exception rate, time-to-recovery, auditability).
Topics: designing for partial data, making confidence and provenance visible, avoiding review-burden features, and choosing when an agent should draft, recommend, or act. Vendor-agnostic, next-sprint focused.
AI in Regulated Enterprise Workflows: Judgment First, Models Second
In regulated enterprise settings, the hard part of AI is rarely training a model. It is deciding what the system is allowed to do, what evidence it must show, and when a human must stay in the loop.
This talk reframes AI product work around judgment: scoping decisions that affect money, compliance, or customer trust; choosing which workflows are safe to automate; and designing governance that does not freeze shipping. Drawing on experience in energy trading software and earlier GenAI infrastructure work (RAG, vector search, LLM orchestration), it contrasts demo-friendly copilots with operator-grade systems that must be auditable and recoverable.
We walk through a simple decision framework: classify the workflow by risk, define the action the AI may recommend or take, specify the evidence trail, and set clear escalation paths. The session also covers how product managers negotiate tradeoffs with engineering, compliance, and customers without turning every release into a committee.
Attendees should leave able to pressure-test any "AI feature" proposal: Is the judgment clear? Is the failure mode acceptable? Can an operator explain why the system acted?
AI in Regulated Enterprise Workflows: Judgment First, Models Second
In regulated enterprise settings, the hard part of AI is rarely training a model. It is deciding what the system is allowed to do, what evidence it must show, and when a human must stay in the loop.
This talk reframes AI product work around judgment: scoping decisions that affect money, compliance, or customer trust; choosing which workflows are safe to automate; and designing governance that does not freeze shipping. Drawing on experience in energy trading software and earlier GenAI infrastructure work (RAG, vector search, LLM orchestration), it contrasts demo-friendly copilots with operator-grade systems that must be auditable and recoverable.
We walk through a simple decision framework: classify the workflow by risk, define the action the AI may recommend or take, specify the evidence trail, and set clear escalation paths. The session also covers how product managers negotiate tradeoffs with engineering, compliance, and customers without turning every release into a committee.
Attendees should leave able to pressure-test any “AI feature” proposal: Is the judgment clear? Is the failure mode acceptable? Can an operator explain why the system acted?
Key Takeaways:
· Start with the decision and risk class, then pick models and tooling
· Governance should enable shipping with guardrails, not block every experiment
· Operator-grade AI needs evidence trails and escalation paths, not only accuracy charts
· Automate recommendations carefully; reserve irreversible actions for higher bar
· Product managers own the judgment frame across eng, compliance, and customers
Shipping AI to People Who Don't Trust AI: Product Lessons from Energy Trading
Traders are quantitative, data-driven, and deeply skeptical of anything they can't interrogate. At Molecule Software, we built AI capabilities into our energy trading platform, letting traders query their portfolios and get AI-powered analysis and recommendations on demand. The feature worked. The adoption didn't come easy.
This session covers what it takes to ship AI to domain experts who will interrogate every output and have the authority to simply ignore it. What product decisions drive adoption when the model is the easy part? What does trust-building look like in a high-stakes, regulated domain? Practical lessons that transfer to any domain where users are experts and the stakes are real.
Shipping AI to People Who Don't Trust AI: Product Lessons from Energy Trading
Most teams building with LLMs can tell you if their system is up or down. Very few can tell you why it gave a wrong answer last Tuesday, or which retrieval step failed silently. This session walks through the end-to-end architecture of a production RAG system on Azure, drawing from experience taking a GenAI platform from zero to 10 enterprise customers.
We'll cover how Azure AI Search handles vector indexing and hybrid retrieval, how to wire it to Azure OpenAI for grounded responses, and the practical decisions that separate a working prototype from something you'd trust with enterprise data. Topics include chunking strategies, embedding pipelines, retrieval quality tuning, and where systems break under production load.
RAG in the Real World: Building Enterprise GenAI Pipelines on Azure
Retrieval-Augmented Generation is everywhere in demos — but production enterprise deployments look very different. In this session, I'll walk through the end-to-end architecture of a real RAG system built on Azure, drawing from my experience taking a GenAI platform from zero to 10 enterprise customers at a YCombinator-backed startup.
We'll cover: how Azure AI Search handles vector indexing and hybrid retrieval, how to wire it to Azure OpenAI for grounded, context-aware responses, and the practical decisions that separate a working prototype from something you'd trust with enterprise data. Topics include chunking strategies, embedding pipelines, retrieval quality tuning, and where the system breaks under production load.
Attendees will leave with a clear mental model of the Azure services involved (Azure AI Search, Azure OpenAI, Azure Blob + data pipelines), a realistic picture of what goes wrong and how to debug it, and a starting architecture they can adapt to their own use case. No prior RAG experience needed — intermediate Azure familiarity is sufficient.
From Prototype to Production: A PM's Guide to Getting LLM Features Shipped
Most organizations don't struggle to build an AI prototype. They struggle to get it into production. The blockers aren't technical — they're organizational: legal wants auditability, compliance wants guardrails, expert users will catch every mistake, and leadership wants to know when the model is wrong.
This session is a product manager's guide to the decisions that determine whether an LLM feature ships or stalls. Drawing on experience building GenAI platforms at a YCombinator-backed startup and leading AI product development at an enterprise SaaS used by hedge funds and Fortune 100 companies, the talk covers: how to scope what the model can and can't own in a high-stakes workflow; how to design evaluation frameworks that satisfy both product and compliance teams; how to communicate model limitations to expert users who will test your system aggressively; and how to build the organizational trust that gets AI features past legal, risk, and the CISO.
Practical and non-commercial, designed for product leaders, AI practitioners, and anyone trying to close the gap between a working demo and a trusted production system.
AI Governance for High-Stakes Platforms: Beyond Responsible AI Checklists
Most AI governance frameworks are written for products where a bad output is embarrassing. In financial services and commodity trading, a bad output can trigger regulatory exposure, erode client trust, or generate incorrect positions.
This talk moves past the checklist approach to examine what AI governance actually looks like when deployed in high-stakes production environments. Drawing on experience deploying AI in an energy trading platform processing nearly $100B in commodity value daily, the session covers: auditability requirements for AI decisions that affect financial positions; model drift detection strategies that catch degradation before users do; rollback protocols that don't require taking down the entire system; and how to design human-in-the-loop checkpoints that preserve oversight without killing the user experience.
The talk is practitioner-led and non-commercial, designed for risk leaders, product security teams, and technology executives who are past the policy stage and trying to operationalize governance in production AI systems.
Key takeaways: a practical architecture for AI auditability in high-value transaction environments; how to detect and respond to model drift without disrupting operations; design patterns for human oversight that scale; and where most enterprise AI governance frameworks break down in practice.
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top