
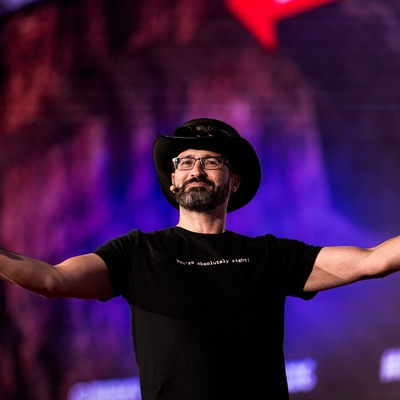
Baruch Sadogursky
Head of DevRel, Port.io
Лид ДевРела
Nashville, Tennessee, United States
Actions
Baruch Sadogursky (@jbaruch) did Java before it had generics, DevOps before there was Docker, and DevRel before it had a name. He built DevRel at JFrog from a ten-person company through an IPO, co-authored "Liquid Software" and "DevOps Tools for Java Developers," and is a Java Champion, a Microsoft MVP for AI, and a CNCF Ambassador alum.
Today he's head of DevRel at Port, working on the agentic SDLC, and a self-certified Level 3 AI Context Sommelier. In addition to sharing knowledge with AI agents, Baruch also shares knowledge with developers through blog posts, meetups, and conferences such as DevNexus, QCon, Kubecon, and Devoxx, mostly on how to use Agentic SDLC platforms to turn off the lights in your software factory once and for all.
Барух Садогурский (@jbaruch) писал на Джаве до того, как в ней появились дженерики, рассказывал про ДевОпс до того, как появился Докер, и занимался ДевРелом до того, как его стали так называть. Барух основал DevRel в JFrog когда там было 10 человек, и помог компании дойти до IPO с оценкой в $6B помогая инженерам лучше делать их работу. Теперь Барух продолжает помогать иженерам, а так же помогает компаниям помогать инженерам. Он соавтор книг "Liquid Software" и "DevOps Tools for Java Developers", является членом ПК нескольких престижных конференций и выступает регулярно на таких конференциях как Kubecon, JavaOne (мир праху его), Devoxx, QCon, DevRelCon, DevOpsDays (по всему миру), DevOops (не опечатка) и так далее.
Badges


Area of Expertise
Topics
Back to the Future of Software: How to Survive the AI Apocalypse with Tests, Prompts, and Specs
Great Scott! The robots are coming for your job—and this time, they brought unit tests. Join Doc and Marty from the Software Future (Baruch and Leonid) as they race back in time to help you fight the machines using only your domain expertise, a well-structured prompt, and a pinch of Gherkin. This keynote is your survival guide for the AI age: how to close the intent-to-prompt chasm before it swallows your roadmap, how to weaponize the Intent Integrity Chain to steer AI output safely, and why the Art of the Possible is your most powerful resistance tool. Expect:
- Bad puns
- Good tests
- Wild demos
The machines may be fast. But with structure, constraint, and a little time travel, you’ll still be the one writing the future.
Engineering Context So AI Stops Guessing
"You're absolutely right," my AI coding agent said, while removing validation logic and confidently explaining why this is an improvement. It agrees when I'm right, agrees when I'm wrong, and will keep agreeing while your production database burns.
The model is fine — it's also working blind, deciding based on whatever you happened to shove into its context window. A cheap, small model with good context consistently outperforms the most expensive frontier model without it — and six months from now, the teams that got their context right will be the ones wondering what the fuss over model upgrades was about.
Three kinds of context artifacts actually work: skills (executable instructions), rules (constraints and conventions), and scripts (deterministic operations) — all versioned, testable, and shareable. We'll start from real failures caused by missing context and rebuild them live on stage: write an artifact, add an eval, watch it fail, iterate until it passes, then publish and install it on a fresh agent. The craft comes down to four things: expertise (encode what you actually know, not vague instructions), feedback loops (measure with evals, iterate), repeatability (version so behavior doesn't drift), and distribution (package so every agent on the team gets the same knowledge).
New talk for 2026 — built from patterns validated across 190+ conference deliveries. The four engineering principles come from the Arc of AI 2026 keynote. Includes live artifact creation and eval demo. Works as 45-min session, keynote, or 90-min hands-on workshop. Solo talk.
The Right 300 Tokens Beat 100k Noisy Ones: Four Context Antipatterns That Kill Your AI Agent
Your agent has the README, the architecture docs, half the issue tracker, and a super prompt that ends with "make no mistakes." A hundred thousand tokens of excellent advice. It still hands back a 500 where the tests wanted a 404.
A bigger context window wouldn't have saved it, because the problem isn't the model, it's the context architecture the model sees.
Baruch will show you four things that quietly wreck that architecture: the stuffed prompt, the wrong tool, the goldfish, and the eval nobody runs. Every one of them is easy to cause and immune to pasting in another document.
Your context window is not a giant socks drawer. Break it into artifacts you can version and test, match the tool to the shape of the problem, and measure what each piece buys you.
And yeah, we'll do it live! It'll be cool if it works and absolutely hilarious if it doesn't.
The session reruns failing agent tasks after each context fix and evaluates the combined changes at the end. Developers can use that approach to test their own context choices. Recorded fallbacks support the live format.
Skill Issue: How to Write Skills That Actually Work
You've written a dozen skills. Some work, some don't, and you have no way to tell which. The agent says "you're absolutely right" while invoking the wrong one, and you keep re-explaining the same things to it. Without a way to measure what a skill adds, there's no way to find out. Meanwhile, the team next door is writing the same ones you already wrote, because nobody can find yours.
If you get why skills matter but can't get yours to do what you want, this is for you. 301, no "what is a skill," straight to the craft.
Skills are context artifacts: prose for flexible guidance, scripts for deterministic work, rules for hard constraints. Let's make them better:
1. A context artifact library that grows and patches itself: new skills emerge from agent friction, existing ones get fixed when they drift.
2. Design evals that grade only what the context adds — scenarios that probe the contribution, rubrics that ignore everything else, guards against state bleed and prompt leakage.
3. Pair every change with a second-model reviewer that catches regressions before merge. Version the library so rollback costs a checkout, not a postmortem.
4. Treat skills like code: scan, sign, gate at install. But also, treat them like prompts: add scanners for the attack surface conventional tooling can't see, like injection in the skill body, indirect poisoning through whatever the skill ingests, and tool-abuse paths that didn't exist before the agent had browsing tools.
5. Build a context artifact supply chain: registry, discovery, telemetry, staged rollout, so the team next door finds your skill instead of writing it for the third time. The same registry that solves discovery solves compliance: one push updates every agent in the org. Measure what proves reuse is real: installation and activation rates, because a skill nobody finds is a skill nobody uses.
Every practice above is itself a skill. "This is how we write context artifacts around here" belongs in the library: versioned, installed on every agent, graded by its own eval. The meta-skill has to earn its tokens too.
New talk for 2026. Scales across formats: 45-min session and 90-min hands-on stay pure 301 — attendees should already know what a skill is; 2- and 3-hour workshops expand the scope to 101→301, opening with the fundamentals (what skills are, how triggers work, installing and invoking them) before the 301 material.
Code-heavy, low-philosophy — targeted at engineers already using agents daily who want to stop repeating themselves. Solo talk.
Like It or Not, You're the CTO Now
Ever had your CTO appear at your desk and ask about the one decision you weren't sure of all month? How the hell did they know to ask about that? You're going to need that ability, because now you have developers reporting to you whether you want it or not - AI coding agents.
You built a nice agentic workflow: your agents write the code and review each other's work. Next, you give them an architect, a tester and a team-lead and you can have a whole software factory running while you do something else, and you go "oh my god". And then you look at what it shipped and ask, "What is this crap?" Annoyingly, the AI reviewers approved all of it.
In this talk Baruch is shownig both how you build your software factory, and how to you run it. What skills from the engineering leadership are directly aplicable to AI context management and how can you gain the uncunny omni-presence ability of a true CTO to ask your agents the right quesitons at the right time.
Developers whose agents write and review code acquire a team to manage. The session applies engineering leadership skills to that team, including the uncanny CTO ability to ask the right question at the right time. Attendees learn how to brief agents and decide when an approval needs human scrutiny.
Let's Fire All the Developers: The 10x Developer Is a Queueing Problem
The headcount spreadsheet says we can fire ninety percent of the developers because an AI coding agent writes ten times more code and appears in the budget as a software subscription. The arithmetic is impeccable.
Remember the promise of firing the testers because DevOps? Automating their tasks was supposed to make the job disappear. That didn't happen.
Eliyahu Goldratt's Theory of Constraints helps us follow where that extra work goes by finding the step holding everything else up. Pass coding to agents and the work piles up in review. Once agents do the reviewing too, the bottleneck moves again. Finding that bottleneck will tell us where we need the developers we were about to fire and what their job is going to look like.
Baruch has been running that experiment on the open-source project, with agents doing the work and one human (barely) in the room. We'll trace the project's history to see what kept waiting after coding and review went to agents. You'll learn how to find the constraint in your own team's work and act on it, with examples of limiting work in progress, reducing batch size, and using agents to expose the decisions that need people.
The talk tests the case for cutting developer headcount against a public project's history. By following the work after agents take over coding and review, engineering leaders learn to locate the constraint before deciding where their developers are needed.
The Agent That Didn't Know Who to Ask
Once upon a time, a company hired a tireless developer who wrote code before breakfast and even used Jira without complaining. They gave their new colleague access to every repository and a license for every tool. Onboarding complete.
A junior developer would have had questions. Who owns payments? Why don't we use that library anymore? Eventually, they'd learn that Alice knows, the incident report explains, and the runbook they found survived two reorganizations because nobody ever followed it.
Our developer is an AI agent. It has to work all of that out too. Except tomorrow, a fresh context window makes it a new hire again. Same impressive résumé, no recollection of orientation. It reconstructs the company from whatever it happens to find, one guessed unbounded MCP call at a time, while burning tokens like it's 2025 and tokenmaxing is still a thing. Yesterday it found Alice, today it found a wiki page written by her predecessor instead, and both answers sounded convincing.
Even if the frontier labs give us an agent that writes great code, who teaches it how we do things around here?
Baruch follows our unfortunate new hire through an organization that assumes access means understanding, and considers what an agent needs to know to work there. How does company knowledge become something an agent can reliably use and reuse, who keeps that knowledge current, and what should still require a conversation with Alice?
Alice is very good at onboarding agents. She calls herself a "prompt engineer" now. But onboarding the same colleague every morning is getting old, even for her.
The talk challenges the assumption that a coding agent is ready to work once it has repository access and tools. A fictional onboarding story makes conflicting company knowledge concrete, with questions about reliable reuse, maintenance, and the decisions that still require a person.
Vibecoding Fast and Slow: Your Brain on AI Agents
As agents take on more of the coding, more of our work involves deciding what they should do and judging the work they return. We may be following several tasks at once, without having written the code ourselves.
It's tempting to hand a task to an agent and mentally cross it off the list, assuming it'll do it as well as we would and on time. With other agents pulling us away to answer questions and check results, we're less likely to challenge that assumption during review. The tests pass, the explanation sounds right, and we click Approve. That's LGTM on AI steroids.
Baruch uses Nobel Laureate Prof. Daniel Kahneman's work on automatic and deliberate thinking, alongside research on attention, fatigue and learning, to examine what working with agents does to our thinking. Experience can make a quick judgment useful, but confidence can also come from an answer that merely sounds familiar.
You'll learn how to decide where deliberate thought is worth the effort, how to build the expertise to judge and debug code an agent writes, and how to arrange work around the limits of human attention. We'll examine what personal habits, team practices and tooling can do to reduce needless effort, improve feedback and help us recover when we're tired.
This talk helps developers and engineering leaders decide which agent results need closer examination, where delegation can cost them practice needed to build expertise, and how to organize work so they have the attention to make those decisions. It brings cognitive research into practical choices about learning, team coordination and feedback from development tools.
Technical Enshittification: Why Everything in IT is Horrible Right Now and How to Fix It
Did you notice how everything in IT is crap right now? Basic apps demand absurd amounts of memory, updates remove features people actually use, and moving a button counts as innovation; add a chatbot and there's a keynote. When Facebook was bragging about breaking things, at least it was to move faster. What's the excuse now?
And when somebody finally tries to fix the mess, they inherit years of decisions nobody can explain. Why does this ugly workaround exist, and is it safe to remove? The code is in Git, the ticket says "done", and the explanation left during the last reorg, so good luck with the refactoring.
Baruch will examine how we get here: incentives that reward shipping over maintaining, reorganizations that scatter responsibility, and technical decisions that outlive everybody who understood them. Each change can look reasonable on its own while making the whole system worse. We call the result technical debt, but a backlog of cleanup tickets won't recover the knowledge we've lost. LLMs love adding documentation to the pile, which looks helpful until finding the answer buried in it becomes as hard as finding the colleague who left.
Baruch will discuss what it takes to keep the reasons behind architectural decisions available to the next developer, along with who owns the service and what depends on it. Someone has to keep that knowledge current and retire what's obsolete, so finding an answer doesn't require an archaeological expedition through generated Markdown.
Fixing the Googles and Metas may be beyond the reach of a conference talk, but there's still time to stop your own project from providing material for the next one.
This talk connects familiar software decay to the incentives and missing decision history that make maintenance difficult. Developers and engineering leaders get a way to examine why their own systems are deteriorating, including what the next maintainer needs to know before removing an ugly workaround.
RoboCoders: Judgment Day: AI Agents Face Off
Two speakers, multiple AI coding agents, real IoT hardware, and a bet: the context you give your agent matters more than which agent you pick.
Live on stage, starting from an empty directory: control IoT devices, build a face recognition pipeline, and drive physical hardware as a real-time visual feedback system with real devices reacting to code written by AI in real time.
The easy parts work fine, but then the hardware and the API disagree about something the documentation doesn't mention, both agents produce code that runs, passes every check, and is completely wrong. We change what the agent knows (using spec-driven development, intent integrity chains, and structured context engineering) and the audience sees exactly what that fixes, what it breaks next, and how the every next failure is worse than the first.
7 deliveries including Devoxx Belgium, Devoxx Poland, JFokus 2026, and BaselOne. Co-presented with Viktor Gamov. Physical IoT hardware on stage — smart bulbs, camera feed, LED light bars respond to face recognition in real time. Audience sees the agents succeed and fail with real devices, not slides. Scales from 45-min (core IoT demo) through 75-min (full stage progression) to 2-3 hours (additional rounds, spec-driven development with iikit/OpenSpec/Kiro, methodology deep dives). Strong closing keynote candidate — the visual spectacle of hardware responding to code written live is a crowd favorite.
Codepocalypse Now: LangChain4j vs JetBrains Koog
Can Java build a real AI agent — one that manages your calendar, reads your email, orders pizza, and remembers who you are across sessions? OpenClaw, the personal AI agent with 350K GitHub stars, proves the concept. We're going to build it twice, in Java, live on stage.
Baruch brings JetBrains Koog, Viktor brings LangChain4j. Same features, same LLM, completely different philosophies. We'll run six competitive rounds of coding, from basic agent setup through memory, tool calling, agentic workflows, guardrails, and observability. Each round surfaces a design disagreement: should memory be an Advisor or a Provider? Are agents composed services or first-class citizens? And when your guardrail framework and the model disagree, who wins?
The frameworks disagree on how AI agents should be built. The audience votes on who's right.
5 deliveries including Devoxx France, Dev2Next, and Arc of AI 2026. Co-presented with Viktor Gamov. Live competitive coding format — two speakers build the same app simultaneously with different frameworks, audience votes on winner. High-energy, high-engagement format. Best in long formats (2-3 hours), can be done as short as 45-min slot. Java/AI track.
Never Trust a Monkey: From AI Slop to Code You Can Ship
We gave the infinite monkeys GPUs, and one of them wrote `assertEquals(true, true)`. The test passed. Naturally, we asked the monkey to review its own work.
When the code, tests, and review can all inherit the same wrong assumption, a second opinion is an expensive way to agree with yourself. Somebody has to establish what correct means before the agent starts explaining why it has achieved it.
We'll challenge the specification before deriving tests from it. Once we've agreed on the assertions, we'll lock them and try to get broken code through by changing its exam. You'll see which checks catch that attempt and where we still depend on a human understanding the requirement.
That agreement also has to survive the trip to production. At the release gate, we'll check who approved the change and whether the passing CI run belongs to the revision we're about to ship. A green run for yesterday's code won't do. If the specification changes, we'll send it back for a decision before treating the new tests as the agreed exam.
"The monkey seemed confident" remains a terrible acceptance criterion.
This session attacks a verification chain by trying to change the tests that judge the generated code. Developers see how to keep the agreed requirement intact through implementation and check that approval and passing CI belong to the revision being released. The release checks are new material.
PortCon 2026 Sessionize Event Upcoming
CNCF-Hosted Co-located Events North America 2026 Sessionize Event Upcoming
AI Native DevCon New York 2026 Sessionize Event Upcoming
BaselOne 2026 Sessionize Event
WeAreDevelopers World Congress 2026 - North America Sessionize Event
AgentCon - Saint Louis Sessionize Event
AgentCon - Miami Sessionize Event
AgentCon - Phoenix Sessionize Event
J-Spring 2026 Sessionize Event
JNation 2026 Sessionize Event
KotlinConf 2026 Sessionize Event
JCON EUROPE 2026 Sessionize Event
Devnexus 2026 Sessionize Event
Voxxed Days Tichino 2026
Technical Enshittification: Why Everything in IT is Horrible Right Now and How to Fix It
Jfokus 2026 Sessionize Event
Open Conf - 2025 / PANELS and OPEN SPACE ACTIVITIES Sessionize Event
AI by the Bay Sessionize Event
DevFest Toulouse 2025 Sessionize Event
J-Fall 2025 Sessionize Event
BaselOne 2025 Sessionize Event
AI fokus Sessionize Event
J-Spring 2025 Sessionize Event
Spring I/O 2025 Sessionize Event
JCON EUROPE 2025 Sessionize Event
IJ Internal Conference 2025 Sessionize Event
Devnexus 2025 Sessionize Event
DevOps Vision and MLOps Vision 2024 Sessionize Event
DevOpsDays Tel Aviv 2023 Sessionize Event
BaselOne 2024 Sessionize Event
JConf.dev 2024 Sessionize Event
swampUP 2024 Sessionize Event
KCDC 2024 Sessionize Event
JNation 2024 Sessionize Event
JCON EUROPE 2024 Sessionize Event
Devnexus 2024 Sessionize Event
DeveloperWeek 2024 Sessionize Event
DevRel Experience 2023 Sessionize Event
DevOps Vision 2023 Sessionize Event
Oπe\n Conf - 2023 Sessionize Event
BaselOne 2023 Sessionize Event
DevOps Days Buffalo 2023 Sessionize Event
Infobip Shift 2023 Sessionize Event
DevOpsDays Birmingham (UK) 2023 Sessionize Event
swampUP 2022 City Tour - Munich Sessionize Event
swampUP 2022 City Tour - London Sessionize Event
swampUP 2022 City Tour - New York City Sessionize Event
Yalla DevOps Tel Aviv 2022 Sessionize Event
JNation 2022 Sessionize Event
swampUP 2022 Sessionize Event
DevOpsDays Austin 2022 Sessionize Event
Cloud Native Kitchen Sessionize Event
DeveloperWeek New York 2020 Sessionize Event
EuropeClouds Summit Sessionize Event
DeveloperWeek Global 2020 Sessionize Event
Azure Day Rome 2020 Sessionize Event
All The Talks Sessionize Event
DevOps Summit Amsterdam 2019 - Two days DevOps experience Sessionize Event
Yalla! DevOps 2019 Sessionize Event
swampUP 2018 Sessionize Event
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top