
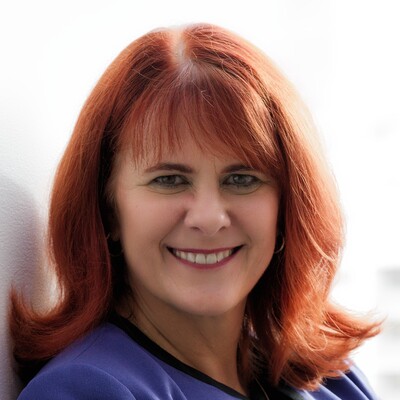
Ginger Grant
Principal and Founder of Desert Isle Group
Phoenix, Arizona, United States
Actions
Ginger Grant is a distinguished Microsoft Data Platform MVP and Microsoft Certified Trainer (MCT), renowned for her deep expertise in advanced analytics, machine learning, AI, data warehousing, and the evolving landscape of Microsoft Fabric. As a sought-after consultant, Ginger empowers organizations to harness the full potential of their data ecosystems.
Beyond consulting, Ginger is a prolific thought leader and speaker for both keynotes and technical training. She contributes regularly as a columnist for Code Magazine, authors insightful books, and shares practical knowledge on her blog, DesertIsleSQL.com. Her educational impact spans a wide range of technologies, including Azure Synapse Analytics, Python, and Azure Machine Learning, making her a trusted voice in the data community.
Whether on stage, in print, or in the classroom, Ginger’s passion for data and commitment to knowledge-sharing make her a standout figure in the world of data and AI.
Links
Badges


Area of Expertise
Topics
Building Agentic AI Systems in Microsoft Fabric
The expectations for AI have grown past the ability to answer questions in a chat bot. People expect AI to do things for them. Agentic AI represents a fundamental shift from passive analytics to systems that can reason, plan, and execute tasks directly against your data estate. In Microsoft Fabric, this evolution is enabled through the combination of Fabric IQ, Data Agents, and Microsoft Foundry, forming a cohesive platform for building intelligent, action-oriented data solutions.
In this session, attendees will learn how Fabric IQ enhances the data experience by embedding AI-driven understanding directly into the platform, enabling natural language interaction, contextual insights, and automated reasoning across OneLake data to examine how Fabric IQ interprets semantic models, metadata, and usage patterns to drive intelligent responses.
The session then dives into Fabric Data Agents, where AI moves from insight generation to task execution. Attendees will see how agents leverage large language models, vector stores, and shared context to perform real operations such as data ingestion, transformation orchestration, SQL generation, governance enforcement, and monitoring.
Finally, we connect these capabilities to Microsoft Foundry, which provides the foundation for building, orchestrating, and governing enterprise-grade AI agents. You will learn how Foundry enables multi-agent collaboration, prompt and model management, and secure deployment patterns that allow agentic solutions to scale beyond Fabric while maintaining control over data access and execution boundaries.
Through live demonstrations and practical design patterns, attendees will build an end-to-end agentic solution that connects Fabric IQ insights, Data Agent execution, and Foundry orchestration. The session emphasizes real-world implementation, including security considerations, role-based access control, and strategies for ensuring agents operate within governed, auditable frameworks.
By the end of this session, you will understand how to move from traditional reporting and automation into fully agent-driven data operations, positioning your organization to take advantage of the next generation of AI inside Microsoft Fabric.
Agentic Development in Microsoft Fabric
This hands-on session teaches Microsoft Fabric developers how take data from different sources and transform it into analytical structures stored in lakehouses or warehouses and semantic models using agentic workflows to orchestrate complex processes. This session shows how to turn AI’s promised productivity gains into disciplined, repeatable practices you can implement immediately in Microsoft Fabric through the use of several different models and tools. We will walk through how to set up an AI-ready environment on your own laptop, along with the tools, libraries, and patterns needed so you can follow along and reuse everything yourself. The session covers how to build prompt libraries, reusable patterns, and guardrails so your results are consistent instead of hit-or-miss.
The course includes an introduction into the use of MCP Servers and CLIs to turn those prompts into agentic processes so you can implement strategies beyond cutting and pasting from chat windows.
Attendees are introduced to AI assisted CI/CD practices to improve governance and release quality. The course demonstrates how AI can assist by developing quality checks with GitHub Actions and enforce standards using AI-assisted code generation and review. These processes can ensure hallucinations don’t see production and ensure you catch issues before your users do.
Attendees will leave with a structured framework, practical automation techniques, and repeatable methods to improve quality, consistency, and delivery speed across your Fabric environment.
Building an AI-Enabled Fabric Practice: Standards, Automation, and Scale
AI promises productivity gains, but real value comes from disciplined implementation. This half-day technical session moves beyond theory and demonstrates how to systematically embed AI and automation into Microsoft Fabric. Technical success alone is not enough. You will learn how to establish standards, build internal prompt libraries, create review processes, and drive adoption across teams so that AI becomes a scalable capability rather than a personal productivity trick.
Attendees will move beyond theory and into practical application, learning what tools and libraries improve Fabric productivity through hands on exercises that put these concepts into practice.
We will explore how AI can be applied to generate test cases, validate calculations, detect inconsistencies, and verify that deployed artifacts meet their original intent. The goal is to reduce defects while increasing delivery speed without sacrificing governance. We will examine how this can be incorporated into many aspects of Fabric, from Notebooks to Semantic models.
Attendees will leave with:
• A structured framework for integrating AI into Fabric development
• Practical GitHub Actions patterns for enforcing standards and automation
• Repeatable methods for moving from specification to semantic model implementation
• AI-assisted testing strategies to improve release quality
• Governance and adoption patterns that scale across teams
This is a hands-on, implementation-focused session designed for architects, data engineers, and BI developers who want to modernize their Microsoft Fabric practice with disciplined AI and automation techniques.
Building an End-to-End Lakehouse Solution
This workshop will provide participants with the knowledge and tools needed to create a enterprise-ready Microsoft Fabric Lakehouse from scratch. The workshop covers everything from getting started gathering data from different sources, transforming the data into an analytical model, securing access, and monitoring it’s performance. As Fabric provides many different methods for performing these tasks, we will cover a variety of different development tools, including using shortcuts, copying data, pipelines, Data Flow Gen 2, notebooks, and explain which is the best choice in a given situation. Participants will practice the steps in hands on exercises using medallion architecture to transform the data into an analytical lakehouse, which can be used for ad-hoc querying, and of course as a source for Power BI reports. Participants will learn how to provide ongoing maintenance, security and monitoring of the lakehouse to ensure it is an enterprise level solution. The workshop experience and examples will provide participants with the knowledge needed to implement the techniques to create their own lakehouse.
By the end of the session, participants will not only understand the technical steps involved but also when and why to choose a lakehouse architecture for their organizational data needs.
Agenda Breakout
Lakehouse architecture and capabilities in Fabric
• Overview of all you can do with a Lakehouse
• Lakehouse physical structure and One Lake
• Parquet and Delta Lake
• Architectural reasons for including a lakehouse
Developing a Lakehouse with Medallion Architecture
• Process Description
• Workspace Organization
• Component organization
Loading Data into a Lakehouse
• Using the copy command
• Shortcuts
• Data Exploration in the Lakehouse with SSMS and Azure Data Studio
Implementing optimal Lakehouse design
• Dimensional modeling
• Transforming data with Pyspark and Spark SQL
• Data flow Gen2
Using a Fabric Lakehouse
• Power BI Direct Lake
• Loading data to a Data Warehouse
• Sharing
• Security
• Monitoring and Performance
• Default and other semantic modeling
CICD in Fabric using Branching, Merging, Migrations and Rollbacks
Source control in Fabric needs to handle a lot, including: multiple people working on features, automatic content checking for pull requests, branching, merging, rollbacks and workspace migration. This session shows how to implement all of it and how to incorporate Variable Libraries and Development Pipelines to make releases as robust as possible even for the unique process of Semantic Models.
Why architecting a Microsoft Fabric Environment may include a Fabric SQL DB
Businesses today want well designed databases which can be used not only by applications but are part of an analytical solution which allows people to interact visually with the data in reports. Are you interested in decreasing and centralizing your Azure costs while continuing to support applications which need a SQL database? Are you interested in migrating an on-premises SQL Server database to the cloud or move away from decentralized manage instance databases? Fabric SQL DB can be the solution as it provides the ability to combine SQL Server functionality with Business Intelligence Analysis.
For many existing applications, having a SQL Database is a requirement. We will review the processes for doing maintenance for SQL DB inside of Microsoft Fabric, focusing on the “knob free” methods to minimize the steps involved and migration from an on prem database. We will examine the different cost models to demonstrate how this solution can be used to minimize costs and decrease management effort through automated maintenance and centralized resource monitoring.
This session will provide you with the use cases to determine when and why an SQL DB inside of Fabric can benefit your data environment.
Lakehouse or Warehouse : Which is the right choice in Microsoft Fabric
Microsoft Fabric introduced the Lakehouse and the Warehouse as two different data structures, but how different are they really? Both cost the same amount to run, both allow access via a SQL Endpoint, use parquet files, include data masking, TSQL querying and other features commonly associated with SQL Server. Why do you want to use one over another? In this session we will look at the architecture decisions which determine which is the best choice in your organization. We will also demonstrate how you can convert a dedicated pool from Azure Synapse DW into a lakehouse. If you want to consolidate your data from a Synapse solution to Microsoft Fabric you will find this session very helpful. We will provide you with reasons for why you might want to consolidate your data and when this architecture might not be the best choice for your environment. If you are looking to design a data architecture for your organization this session will help you make the right decisions going forward.
Building an Fabric Environment for Power BI
Microsoft Fabric contains a number of different tools which you can use to create a data lake house environment perfect for Power BI. Learn the steps that are involved to develop and monitor data transformation pipelines, create a data lake house environment, and produce a final data store. Depending on the different data elements within the organization, the final data store could be a lakehouse, SQL Endpoint, data warehouse or Power BI model. We will review the different use cases so that users will understand which combination is best given properties of data and skillsets in your environment.
Implementing Data Analytics with Microsoft Fabric
Microsoft Fabric has incorporated a number of different elements into one environment for data lakes with OneLake, data warehousing, machine learning, data transformation, and reporting. In this session we will look at using OneLake for data lakehouses and demonstrating how OneLake can be used instead of a database highlighting the performance improvements which have been made. Demonstrations will show the ability to use Fabric to connect to data from different sources and from different data lakes to ensure compliance with GDPR or other location-based regulations with OneLake. We will examine what a Fabric data lakehouse entails and how the data is integrated into Power BI for reporting. Changes in Spark clusters and Delta file implementation are examined to ensure you will understand how these improvements will impact your data movement pipelines and machine learning tasks. Data science workflows are reviewed to provide a good explanation of not only how to use them, but also the best practices for integrating these objects into pipelines. We will investigate how using the new Dataflow2 data transformations can speed up development and when they would be a good implementation choice. We will also examine the different ways Copilot is incorporated within Fabric so that your organization can be on the cutting edge of AI development with ChatGPT technology. This session will show you how to leverage Fabric’s different components for data driven decision making within your organization.
Architecting a data solution in Fabric
With the introduction of Microsoft Fabric, the methods used for creating a data lake and using it in Power BI have changed. In this session we will take a look at how you can use the different components of Fabric to Architect a solution using the features of One lake with a Fabric workload. The session focuses on different elements within Fabric and how you can used them to create a solution which starts with bringing in your data, creating a scalable process to transform the data into analytical models which can be used for different kinds of analysis of course including reporting with Power BI.
Data Engineering in Microsoft Fabric
Microsoft Fabric includes a lot of different elements, including Data Engineering. Data Engineering includes notebooks, pipelines, lakehouses and data pipelines which you will have a better understanding of how they work together within fabric. In the demos for this session you will see what functionality these elements provide and how you can use them in your data solutions.
Fabric Data Security in Lakehouses and Data Warehouse
When data moves from a database to a lakehouse or a warehouse, how to you secure the data? How do you provide access to it? Can you implement row level security on the the lakehouse? Can you mask the data and have it the data appear as masked inside of a Semantic Model used for Power BI reporting? In this session, you will learn how you can implement security on lakehouses and data warehouses inside of Fabric and which one you should implement with your data. You will learn how to restrict access to data and how to implement object and row level security at the database level. See how you can implement similar user security to what you may have deployed in SQL Server inside of Fabric Endpoints in SQL Server Managment Studio
Checking out Variable Libraries in Fabric
Microsoft added variable libraries on April 1 to markedly improve the development pipeline experience, which greatly improves the entire CICD process for releasing content in Fabric. Now to make variable libraries work, parameters need to be implemented throughout pipelines, notebooks and semantic models. These parameters will be changed when items are moved using Development Pipelines. While development pipelines were originally created for Power BI using them to deploy Fabric content were problematic, but with Variable Pipelines, they are the best way to migrate code from dev to test to prod.
There are a few interesting exceptions that I want to highlight for creating and deploying your own semantic models. There are different processing issues that direct lake semantic models have that you will need to know if you want to implement a solution with them.
We will explore the foundational concepts of parameter usage in Fabric, demonstrating how to define, manage, and adjust parameters to for different environments. The session will highlight best practices for incorporating variable libraries, showcasing their role in facilitating seamless updates across multiple notebooks and pipelines.
Attendees will gain insights into:
• The architecture and benefits of using parameters in Fabric environments.
• Step-by-step guidance on setting up and utilizing variable libraries.
• Real-world examples illustrating the impact of parameterization on workflow efficiency.
By the end of this talk, participants will be equipped with the knowledge and tools to enhance their data engineering practices, leveraging the full potential of parameters and variable libraries in Fabric to drive more efficient and scalable data solutions.
Building Generative AI models with SQL Server 2025
Building Generative AI Solutions with SQL Server 2025
SQL Server 2025 introduces native support for vector storage and AI-driven query capabilities, fundamentally changing how generative AI solutions can be built within the database engine. Rather than exporting data to external platforms or introducing complex data movement pipelines, organizations can now design and operationalize AI workloads directly where their data already resides.
In this session, you will learn how to leverage SQL Server 2025’s built-in vector architecture to store embeddings, perform similarity searches, and power retrieval-augmented generation (RAG) scenarios using your enterprise data. We will walk through the new T-SQL AI syntax that allows you to integrate large language models into standard query workflows, enabling tasks such as semantic search, summarization, and contextual question answering without leaving the SQL environment.
You will see how to configure and connect to the AI model of your choice, including how to define model endpoints, control where models are hosted, and manage inference execution within SQL Server. The session focuses on practical implementation, showing how to design production-ready patterns that combine relational data with vector-based intelligence while maintaining governance, security, and performance.
By the end of this session, you will understand how to build, deploy, and scale generative AI solutions natively in SQL Server 2025, eliminating unnecessary architecture complexity and bringing AI directly to your data platform.
T‑SQL Notebooks in Microsoft Fabric
Microsoft Fabric provides the ability to use many different elements, including T-SQL to provide abilities for developers to leverage skills they already possess combined with new tools. In this session, you learn how to create T-SQL notebooks for pipelines and write T-SQL with Python to directly update lakehouses and warehouses in Microsoft Fabric.
The session demonstrates practical development techniques including reusable code templates, integrated charting, notebook automation possibilities, and hybrid workflows that combine Python and T-SQL together in the same Fabric environment.
Whether you are modernizing SQL development practices, documenting analytical workflows, or building repeatable Fabric data solutions, T-SQL notebooks provide a modern approach to SQL development inside Microsoft Fabric. Attendees leave with practical guidance, real-world use cases, and a strong understanding of where T-SQL notebooks fit into the broader Fabric analytics ecosystem.
Learning Objectives
1. Understand how to create, configure, and execute T-SQL notebooks within Microsoft Fabric for pipelines.
2. Learn how to combine T-SQL code, in pyspark to improve collaboration and workflow documentation.
3. Explore practical use cases for T-SQL notebooks including query development, data exploration, automation workflows, and integrated analytics solutions within Microsoft Fabric
SQL Saturday Jacksonville #1041 Sessionize Event
SQLBits 2023 - General Sessions Sessionize Event
Microsoft Azure + AI Conference Fall 2022 Sessionize Event
Data Toboggan - Cool Runnings 2022 Sessionize Event
SQL & Azure SQL Conference Spring 2022 Sessionize Event
SQLBits 2022 Sessionize Event
Data.Toboggan 2022 Sessionize Event
Live! 360 Orlando 2021 Sessionize Event
PASS Data Community Summit 2021 Sessionize Event
Global AI Back Together - Cleveland 2021 Sessionize Event
The North American Collaboration Summit 2021 Sessionize Event
Virtual 2021 Data.SQL.Saturday.LA Sessionize Event
Data.Toboggan - Cool Runnings Sessionize Event
Data Céilí 2021 Sessionize Event
Cloud Lunch and Learn Marathon 2021 Sessionize Event
Ginger Grant
Principal and Founder of Desert Isle Group
Phoenix, Arizona, United States
Links
Actions
Please note that Sessionize is not responsible for the accuracy or validity of the data provided by speakers. If you suspect this profile to be fake or spam, please let us know.
Jump to top